A Spark developer wants to improve the performance of an existing PySpark UDF that runs a hash function that is not available in the standard Spark functions library. The existing UDF code is:
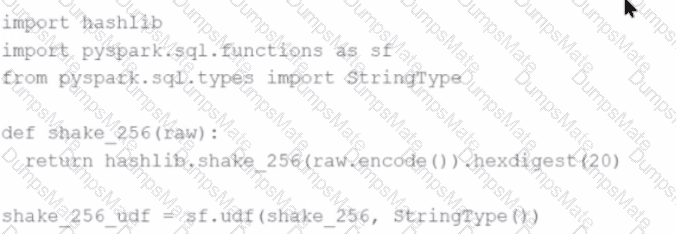
import hashlib
import pyspark.sql.functions as sf
from pyspark.sql.types import StringType
def shake_256(raw):
return hashlib.shake_256(raw.encode()).hexdigest(20)
shake_256_udf = sf.udf(shake_256, StringType())
The developer wants to replace this existing UDF with a Pandas UDF to improve performance. The developer changes the definition of shake_256_udf to this:CopyEdit
shake_256_udf = sf.pandas_udf(shake_256, StringType())
However, the developer receives the error:
What should the signature of the shake_256() function be changed to in order to fix this error?