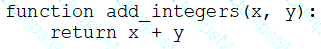
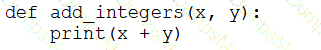
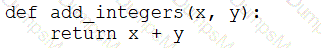
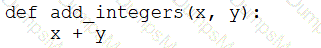
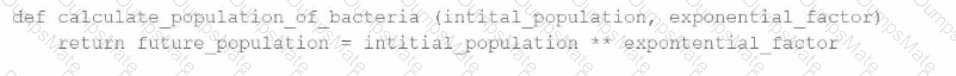
Halloween Sale Special - 75% Discount Offer - Ends in 0d 00h 00m 00s - Coupon code: 75only

Databricks-Certified-Data-Engineer-Associate Databricks Certified Data Engineer Associate Exam Questions and Answers

Questions 4

A single Job runs two notebooks as two separate tasks. A data engineer has noticed that one of the notebooks is running slowly in the Job’s current run. The data engineer asks a tech lead for help in identifying why this might be the case.

Which of the following approaches can the tech lead use to identify why the notebook is running slowly as part of the Job?

Options:

A.

They can navigate to the Runs tab in the Jobs UI to immediately review the processing notebook.

B.

They can navigate to the Tasks tab in the Jobs UI and click on the active run to review the processing notebook.

C.

They can navigate to the Runs tab in the Jobs UI and click on the active run to review the processing notebook.

D.

There is no way to determine why a Job task is running slowly.

E.

They can navigate to the Tasks tab in the Jobs UI to immediately review the processing notebook.

Buy Now
Questions 5

What are the transformations typically included in building the Bronze layer ?

Options:

A.

Perform extensive data cleansing

B.

Aggregate data from multiple sources

C.

Business rules and transformations

D.

Include columns Load date/time, process ID

Buy Now

Databricks-Certified-Data-Engineer-Associate Report Card

Questions 6

A new data engineering team team has been assigned to an ELT project. The new data engineering team will need full privileges on the table sales to fully manage the project.

Which command can be used to grant full permissions on the database to the new data engineering team?

Options:

A.

grant all privileges on table sales TO team;

B.

GRANT SELECT ON TABLE sales TO team;

C.

GRANT SELECT CREATE MODIFY ON TABLE sales TO team;

D.

GRANT ALL PRIVILEGES ON TABLE team TO sales;

Buy Now
Questions 7

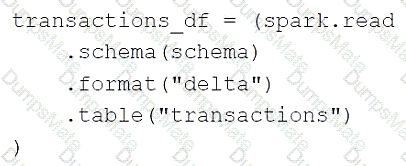
A data engineer is using the following code block as part of a batch ingestion pipeline to read from a composable table:

Databricks-Certified-Data-Engineer-Associate Question 7

Which of the following changes needs to be made so this code block will work when the transactions table is a stream source?

Options:

A.

Replace predict with a stream-friendly prediction function

B.

Replace schema(schema) with option ( " maxFilesPerTrigger " , 1)

C.

Replace " transactions " with the path to the location of the Delta table

D.

Replace format( " delta " ) with format( " stream " )

E.

Replace spark.read with spark.readStream

Buy Now
Questions 8

Which Databricks SQL predicate correctly performs a null-safe equality comparison so that rows are matched when both sides are NULL or when both are equal non-NULL values?

Options:

A.

WHERE customer_id < = > :cid

B.

WHERE customer_id = :cid

C.

WHERE customer_id < > :cid OR customer_id IS NULL

D.

WHERE COALESCE(customer_id, ' ' ) = COALESCE(:cid, ' ' )

Buy Now
Questions 9

A data engineering team is designing the Gold layer in its Unity Catalog-governed lakehouse for downstream BI and analytics users. The team wants to expose business-ready metrics with fast query performance and consistent definitions while keeping the transformation logic in Spark notebooks.

Which type of Gold-layer object meets this requirement?

Options:

A.

A materialized view that precomputes aggregations from Silver tables on a schedule and is queried by BI tools for faster, consistent analytics

B.

A view that directly references raw Bronze tables so BI tools can define their own joins and aggregations

C.

A streaming table that continuously ingests raw events from source systems and exposes them directly to BI users

D.

A collection of CSV files stored in cloud object storage that BI users parse to query the Gold-layer data

Buy Now
Questions 10

A data engineer needs to ingest JSON change data from Salesforce into Unity Catalog-governed Delta tables using a low-code, fully managed experience.

Which Databricks capability should the data engineer use?

Options:

A.

A Lakeflow Connect managed Salesforce connector that writes to Unity Catalog Delta tables.

B.

The Salesforce REST API in a PySpark notebook to query changed records and write them to Delta tables.

C.

Auto Loader with a file-arrival trigger monitoring DBFS.

D.

Auto Loader reading JSON files from an Amazon S3 bucket populated by a separate Salesforce export process.

Buy Now
Questions 11

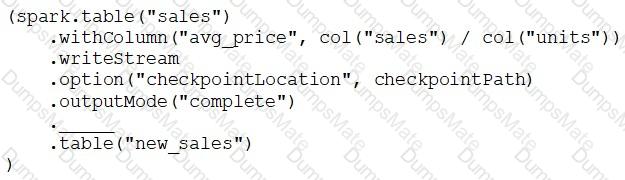
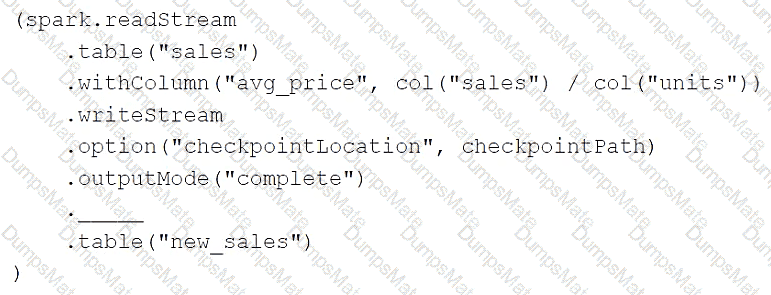
A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.

The cade block used by the data engineer is below:

Databricks-Certified-Data-Engineer-Associate Question 11

If the data engineer only wants the query to execute a micro-batch to process data every 5 seconds, which of the following lines of code should the data engineer use to fill in the blank?

Options:

A.

trigger( " 5 seconds " )

B.

trigger()

C.

trigger(once= " 5 seconds " )

D.

trigger(processingTime= " 5 seconds " )

E.

trigger(continuous= " 5 seconds " )

Buy Now
Questions 12

A data engineer is maintaining an ETL pipeline code with a GitHub repository linked to their Databricks account. The data engineer wants to deploy the ETL pipeline to production as a databricks workflow.

Which approach should the data engineer use?

Options:

A.

Databricks Asset Bundles (DAB) + GitHub Integration

B.

Maintain workflow_config.j son and deploy it using Databricks CLI

C.

Manually create and manage the workflow in Ul

D.

Maintain workflow_conf ig. json and deploy it using Terraform

Buy Now
Questions 13

A data engineer needs to enforce row-level security on main.secure.events(region STRING, event_id STRING). Members of the account group all_regions must see all rows. All other users must see only rows where region = ' EU ' .

Which SQL sequence satisfies the requirement?

Options:

A.

CREATE FUNCTION main.secure.region_filter(region STRING)

RETURN IF(is_account_group_member( ' all_regions ' ), true, region = ' EU ' );

ALTER TABLE main.secure.events

SET ROW FILTER main.secure.region_filter ON (region);

B.

CREATE FUNCTION main.secure.region_filter(region STRING)

RETURN IF(is_account_group_member( ' all_regions ' ), true, region = ' EU ' );

ALTER TABLE main.secure.events

ALTER COLUMN region

SET MASK main.secure.region_filter;

C.

CREATE FUNCTION main.secure.region_filter(region STRING)

RETURN IF(is_account_group_member( ' all_regions ' ), true, region = ' EU ' );

ALTER VIEW main.secure.events

SET ROW FILTER main.secure.region_filter ON (region);

D.

CREATE FUNCTION main.secure.region_filter(region STRING)

RETURN IF(is_account_group_member( ' all_regions ' ), true, region = ' EU ' );

ALTER TABLE main.secure.events

SET ROW FILTER main.secure.region_filter USING COLUMNS (region);

Buy Now
Questions 14

A data engineer is using the OPTIMIZE command on a Delta table. What happens when OPTIMIZE is run twice on the same table with the same data?

Options:

A.

It further reduces file sizes by re-clustering the data

B.

Triggers a full liquid clustering process

C.

Changes the number of tuples per file significantly

D.

It has no effect because it is idempotent.

Buy Now
Questions 15

A data engineer ingests semi-structured JSON logs into a Delta table using Auto Loader with schema evolution enabled. A new string field named userAgent appears in the JSON source data.

What happens to the new userAgent field?

Options:

A.

Ingestion fails with a schema-mismatch error until the table is manually altered.

B.

All existing data is backfilled with a default value for userAgent, and the column is made non-nullable.

C.

The userAgent field is added as a new nullable column in the Delta table and populated for new data.

D.

The userAgent field is silently ignored, and its data is dropped from all new files.

Buy Now
Questions 16

Which of the following SQL keywords can be used to convert a table from a long format to a wide format?

Options:

A.

PIVOT

B.

CONVERT

C.

WHERE

D.

TRANSFORM

E.

SUM

Buy Now
Questions 17

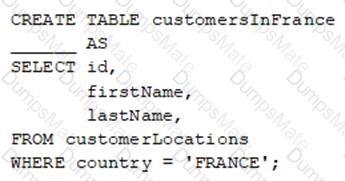
A data engineer wants to create a new table containing the names of customers that live in France.

They have written the following command:

Databricks-Certified-Data-Engineer-Associate Question 17

A senior data engineer mentions that it is organization policy to include a table property indicating that the new table includes personally identifiable information (PII).

Which of the following lines of code fills in the above blank to successfully complete the task?

Options:

A.

There is no way to indicate whether a table contains PII.

B.

" COMMENT PII "

C.

TBLPROPERTIES PII

D.

COMMENT " Contains PII "

E.

PII

Buy Now
Questions 18

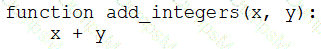
A data engineer that is new to using Python needs to create a Python function to add two integers together and return the sum?

Which of the following code blocks can the data engineer use to complete this task?

A)

Databricks-Certified-Data-Engineer-Associate Question 18

B)

Databricks-Certified-Data-Engineer-Associate Question 18

C)

Databricks-Certified-Data-Engineer-Associate Question 18

D)

Databricks-Certified-Data-Engineer-Associate Question 18

E)

Databricks-Certified-Data-Engineer-Associate Question 18

Options:

A.

Option A

B.

Option B

C.

Option C

D.

Option D

E.

Option E

Buy Now
Questions 19

A data engineer configures a Databricks Lakeflow Job for daily customer data processing:

    Entry task: A single notebook loads raw data.

    Parallel tasks:

      A SQL query task performs data cleansing.

      A notebook task performs feature engineering.

      A pipeline task performs model updates.

Exit task: A dashboard refresh must run after all parallel tasks complete.

Requirement: Implement this dependency pattern using a DAG-based task graph.

Which task configuration ensures that all parallel tasks complete before the dashboard refresh task runs?

Options:

A.

Configure the parallel tasks with sequential dependencies so that each task waits for the previous task to finish.

B.

Add the dashboard task as dependent on all three parallel tasks using fan-in control flow.

C.

Set the dashboard task to depend only on the SQL query task; the other tasks run independently.

D.

Create separate Lakeflow Jobs for each parallel task and trigger them sequentially using external orchestration.

Buy Now
Questions 20

A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.

The code block used by the data engineer is below:

Databricks-Certified-Data-Engineer-Associate Question 20

If the data engineer only wants the query to process all of the available data in as many batches as required, which of the following lines of code should the data engineer use to fill in the blank?

Options:

A.

processingTime(1)

B.

trigger(availableNow=True)

C.

trigger(parallelBatch=True)

D.

trigger(processingTime= " once " )

E.

trigger(continuous= " once " )

Buy Now
Questions 21

A data engineer has a Declarative Automation Bundle with a job resource keyed as etl_job in databricks.yml. After running databricks bundle deploy, the job appears in the workspace but has not executed.

Which command triggers execution of the deployed job?

Options:

A.

databricks bundle deploy run

B.

databricks jobs submit --json < config >

C.

databricks bundle execute etl_job

D.

databricks bundle run etl_job

Buy Now
Questions 22

A data engineer needs to use a Delta table as part of a data pipeline, but they do not know if they have the appropriate permissions.

In which of the following locations can the data engineer review their permissions on the table?

Options:

A.

Databricks Filesystem

B.

Jobs

C.

Dashboards

D.

Repos

E.

Data Explorer

Buy Now
Questions 23

Which compute option should be chosen in a scenario where small-scale ad hoc Python scripts need to be run at high frequency and should wind down quickly after these queries have finished running?

Options:

A.

All-purpose cluster

B.

Job cluster

C.

Serverless compute

D.

SQL Warehouse

Buy Now
Questions 24

A data engineer is designing a Bronze-to-Silver pipeline on the Databricks Data Intelligence Platform. The source system sends daily CSV files, and new optional columns are added over time.

The engineer needs a storage format and table capabilities that provide all of the following:

    Writes that do not conform to the defined schema are rejected.

    The schema can evolve to include new optional columns without manually recreating the table.

    Previous table versions can be queried for debugging and auditing.

Which solution fulfills these requirements?

Options:

A.

Use a Parquet table with Spark’s default schema inference and rerun the job whenever the schema changes.

B.

Use a Delta table with schema enforcement and recreate the table whenever new columns are added.

C.

Use an external table with Auto Loader schema inference for the CSV files.

D.

Use a Delta table with its native schema enforcement, schema evolution, and table-history capabilities.

Buy Now
Questions 25

A data engineer is working in a Python notebook on Databricks to process data, but notices that the output is not as expected. The data engineer wants to investigate the issue by stepping through the code and checking the values of certain variables during execution.

Which tool should the data engineer use to inspect the code execution and variables in real-time?

Options:

A.

Python Notebook Interactive Debugger

B.

Cluster Logs

C.

SQL Analytics

D.

Job Execution Dashboard

Buy Now
Questions 26

A data engineer uses the Databricks workspace UI with Unity Catalog enabled. In Catalog Explorer, they select catalog corp_marketing, then schema campaigns, and see table email_stats. The engineer must let the growth-analysts group read email_stats from its SQL warehouses, but not create, alter, or delete any objects in corp_marketing or campaigns.

Which action sequence meets the requirement?

Options:

A.

On schema campaigns, grant USE SCHEMA and SELECT; then grant SELECT on table email_stats.

B.

On catalog corp_marketing, grant USE CATALOG and CREATE SCHEMA; on schema campaigns, grant USE SCHEMA; then grant SELECT on email_stats.

C.

On catalog corp_marketing, grant USE CATALOG; on schema campaigns, grant USE SCHEMA; then grant SELECT on email_stats.

D.

On schema campaigns, grant USE SCHEMA; then grant SELECT and MODIFY on email_stats.

Buy Now
Questions 27

A data engineer is working on a personal laptop and needs to perform complex transformations on data stored in a Delta Lake on cloud storage. The engineer decides to use Databricks Connect to interact with Databricks clusters and work in their local IDE.

How does Databricks Connect enable the engineer to develop, test, and debug code seamlessly on their local machine while interacting with Databricks clusters?

Options:

A.

By allowing direct execution of Spark jobs from the local machine without needing a network connection

B.

By providing a local environment that mimics the Databricks runtime, enabling the engineer to develop, test, and debug code using a specific IDE that is required by Databricks

C.

By providing a local environment that mimics the Databricks runtime, enabling the engineer to develop, test, and debug code using their preferred ide

D.

By providing a local environment that mimics the Databricks runtime, enabling the engineer to develop, test, and debug code only through Databricks ' own web interface

Buy Now
Questions 28

Which single Databricks CLI command deploys local bundle assets to the target workspace specified in the bundle configuration file?

Options:

A.

databricks bundle validate

B.

databricks bundle plan & & databricks bundle run

C.

databricks bundle deploy

D.

databricks bundle init & & databricks bundle deployment

Buy Now
Questions 29

A governance team is evaluating whether to use Unity Catalog attribute-based access control policies or manually applied row filters and column masks to protect sensitive data across its catalog.

Why should the team use attribute-based access control policies instead of manually applied row filters and column masks?

Options:

A.

Attribute-based access control policies use governed tags to dynamically match tables and columns, so one catalog-level policy can apply to matching current and future objects without per-table configuration.

B.

Attribute-based access control policies can be applied to views and materialized views, whereas manually applied row filters and column masks can only be applied to tables.

C.

Attribute-based access control policies support applying multiple distinct row filters to the same table for one user at query time, whereas manually applied row filters are limited to one filter per table.

D.

Attribute-based access control policies allow row filters and column masks to be written directly in Python and Scala, whereas manually applied filters and masks can use only SQL user-defined functions.

Buy Now
Questions 30

A data engineer is writing a script that is meant to ingest new data from cloud storage. In the event of the Schema change, the ingestion should fail. It should fail until the changes downstream source can be found and verified as intended changes.

Which command will meet the requirements?

Options:

A.

addNewColumns

B.

failOnNewColumns

C.

rescue

D.

none

Buy Now
Questions 31

A data engineer runs df.toPandas() on a wide DataFrame containing 50 million rows. The notebook cell fails with a java.lang.OutOfMemoryError on the driver.

Which memory configuration is directly associated with this failure?

Options:

A.

spark.sql.shuffle.partitions is too high.

B.

spark.memory.fraction is too low.

C.

spark.executor.memory is too low.

D.

spark.driver.memory is too low to hold the collected result.

Buy Now
Questions 32

A data engineer has finished developing a new Declarative Automation Bundle, formerly known as a Databricks Asset Bundle, for a streaming pipeline. The engineer must verify that the configuration is syntactically correct, deploy the code to the workspace, and finally trigger the pipeline to confirm that it runs as expected.

Which sequence of Databricks CLI commands performs these steps in the correct order?

Options:

A.

databricks bundle init → databricks bundle deploy → databricks bundle run

B.

databricks bundle validate → databricks bundle deploy → databricks bundle run

C.

databricks bundle validate → databricks bundle sync → databricks bundle execute

D.

databricks bundle check → databricks bundle upload → databricks bundle start

Buy Now
Questions 33

A data engineering team has noticed that their Databricks SQL queries are running too slowly when they are submitted to a non-running SQL endpoint. The data engineering team wants this issue to be resolved.

Which of the following approaches can the team use to reduce the time it takes to return results in this scenario?

Options:

A.

They can turn on the Serverless feature for the SQL endpoint and change the Spot Instance Policy to " Reliability Optimized. "

B.

They can turn on the Auto Stop feature for the SQL endpoint.

C.

They can increase the cluster size of the SQL endpoint.

D.

They can turn on the Serverless feature for the SQL endpoint.

E.

They can increase the maximum bound of the SQL endpoint ' s scaling range

Buy Now
Questions 34

A data engineer has a Python notebook in Databricks, but they need to use SQL to accomplish a specific task within a cell. They still want all of the other cells to use Python without making any changes to those cells.

Which of the following describes how the data engineer can use SQL within a cell of their Python notebook?

Options:

A.

It is not possible to use SQL in a Python notebook

B.

They can attach the cell to a SQL endpoint rather than a Databricks cluster

C.

They can simply write SQL syntax in the cell

D.

They can add %sql to the first line of the cell

E.

They can change the default language of the notebook to SQL

Buy Now
Questions 35

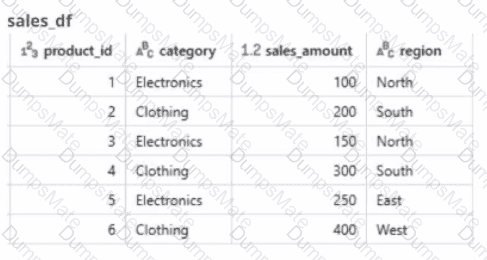
A global retail company sells products across multiple categories (e.g.. Electronics, Clothing) and regions (e.g.. North. South, East. West). The sales team has provided the data engineer with a PySpark dataframe named sales_df as below and the team wants the data engineer to analyze the sales data to help them make strategic decisions.

Databricks-Certified-Data-Engineer-Associate Question 35

Options:

A.

Category_sales = sales df.groupBy( " category " ).agg(sum( " sales amount " ) .alias ( " total sales amount " ))

B.

Category_sales = sales_df.sum( " 3ales_amount " ). g-1- upBy( " categcryn).alias( " toLal_sales_amount))

C.

Category_sale: .es df -agg (sum ( " sales amount " ) .-;r*i:rRy ( " category " ) .alias ( " total sa.en amount " ))

D.

Category_sales = sales_df.groupBy( " reqion " ). agq(sum( " sales_amountn).alias(ntotal_sales_amount ' ' ))

Buy Now
Questions 36

Which of the following commands will return the number of null values in the member_id column?

Options:

A.

SELECT count(member_id) FROM my_table;

B.

SELECT count(member_id) - count_null(member_id) FROM my_table;

C.

SELECT count_if(member_id IS NULL) FROM my_table;

D.

SELECT null(member_id) FROM my_table;

E.

SELECT count_null(member_id) FROM my_table;

Buy Now
Questions 37

A data engineer needs access to a table new_table, but they do not have the correct permissions. They can ask the table owner for permission, but they do not know who the table owner is.

Which of the following approaches can be used to identify the owner of new_table?

Options:

A.

Review the Permissions tab in the table ' s page in Data Explorer

B.

All of these options can be used to identify the owner of the table

C.

Review the Owner field in the table ' s page in Data Explorer

D.

Review the Owner field in the table ' s page in the cloud storage solution

E.

There is no way to identify the owner of the table

Buy Now
Questions 38

Which of the following data workloads will utilize a Gold table as its source?

Options:

A.

A job that enriches data by parsing its timestamps into a human-readable format

B.

A job that aggregates uncleaned data to create standard summary statistics

C.

A job that cleans data by removing malformatted records

D.

A job that queries aggregated data designed to feed into a dashboard

E.

A job that ingests raw data from a streaming source into the Lakehouse

Buy Now
Questions 39

A Delta Live Table pipeline includes two datasets defined using STREAMING LIVE TABLE. Three datasets are defined against Delta Lake table sources using LIVE TABLE.

The table is configured to run in Production mode using the Continuous Pipeline Mode.

Assuming previously unprocessed data exists and all definitions are valid, what is the expected outcome after clicking Start to update the pipeline?

Options:

A.

All datasets will be updated at set intervals until the pipeline is shut down. The compute resources will persist to allow for additional testing.

B.

All datasets will be updated once and the pipeline will persist without any processing. The compute resources will persist but go unused.

C.

All datasets will be updated at set intervals until the pipeline is shut down. The compute resources will be deployed for the update and terminated when the pipeline is stopped.

D.

All datasets will be updated once and the pipeline will shut down. The compute resources will be terminated.

E.

All datasets will be updated once and the pipeline will shut down. The compute resources will persist to allow for additional testing.

Buy Now
Questions 40

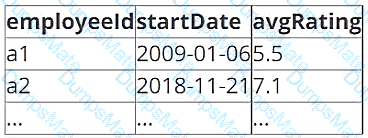
A data architect has determined that a table of the following format is necessary:

Databricks-Certified-Data-Engineer-Associate Question 40

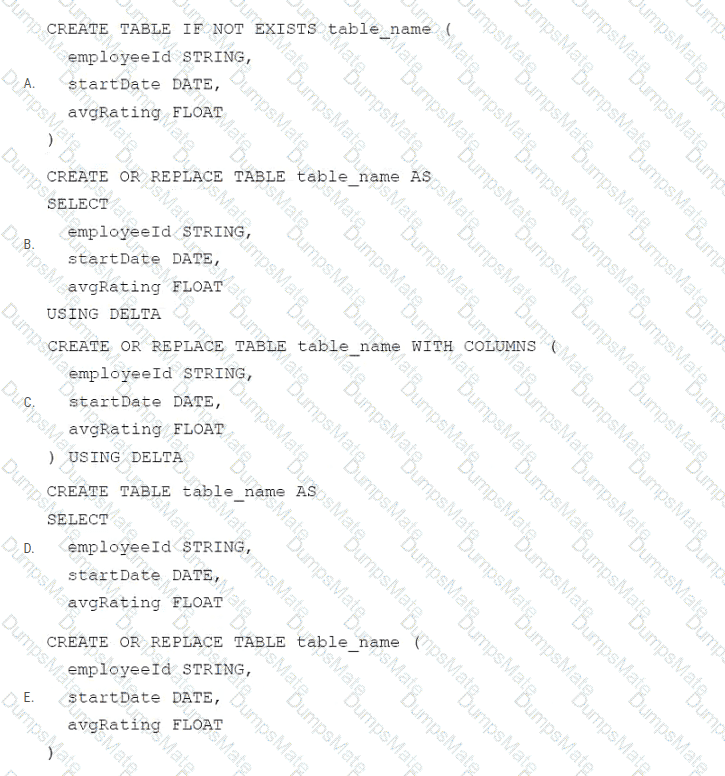
Which of the following code blocks uses SQL DDL commands to create an empty Delta table in the above format regardless of whether a table already exists with this name?

Databricks-Certified-Data-Engineer-Associate Question 40

Options:

A.

Option A

B.

Option B

C.

Option C

D.

Option D

E.

Option E

Buy Now
Questions 41

Which of the following Git operations must be performed outside of Databricks Repos?

Options:

A.

Commit

B.

Pull

C.

Push

D.

Clone

E.

Merge

Buy Now
Questions 42

A data engineer is inspecting an ETL pipeline based on a Pyspark job that consistently encounters performance bottlenecks. Based on developer feedback, the data engineer assumes the job is low on compute resources. To pinpoint the issue, the data engineer observes the Spark Ul and finds out the job has a high CPU time vs Task time.

Which course of action should the data engineer take?

Options:

A.

High CPU time vs Task time means an under-utilized cluster. The data engineer may need to repartition data to spread the jobs more evenly throughout the cluster.

B.

High CPU time vs Task time means efficient use of cluster and no change needed

C.

High CPU time vs Task time means over-utilized memory and the need to increase parallelism

D.

High CPU time vs Task time means a CPU over-utilized job. The data engineer may need to consider executor and core tuning or resizing the cluster

Buy Now
Questions 43

A data engineering team uses Declarative Automation Bundles, formerly known as Databricks Asset Bundles, to deploy the same codebase across development, test, and production environments. The team wants environment-specific behavior to be applied only through bundle configuration, without modifying notebooks, job definitions, or deployment logic during promotion.

Which approach applies environment-specific configuration while meeting this requirement?

Options:

A.

Deploy the same bundle once and edit job settings in the workspace UI for each environment after deployment.

B.

Define bundle variables and reference them from bundle resources, and then override the variable values for each environment using bundle targets.

C.

Use separate Git branches for each environment so each branch can contain environment-specific configuration values.

D.

Parameterize environment-specific values inside notebooks and set those parameters whenever each job run is triggered.

Buy Now
Questions 44

A data engineer has written a function in a Databricks Notebook to calculate the population of bacteria in a given medium.

Databricks-Certified-Data-Engineer-Associate Question 44

Analysts use this function in the notebook and sometimes provide input arguments of the wrong data type, which can cause errors during execution.

Which Databricks feature will help the data engineer quickly identify if an incorrect data type has been provided as input?

Options:

A.

The Data Engineer should add print statements to find out what the variable is.

B.

The Databricks debugger enables breakpoints that will raise an error if the wrong data type is submitted

C.

The Spark User interface has a debug tab that contains the variables that are used in this session.

D.

The Databricks debugger enables the use of a variable explorer to see at a glance the value of the variables.

Buy Now
Questions 45

An organization plans to share a large dataset stored in a Databricks workspace on AWS with a partner organization whose Databricks workspace is hosted on Azure. The data engineer wants to minimize data transfer costs while ensuring secure and efficient data sharing.

Which strategy will reduce data egress costs associated with cross-cloud data sharing?

Options:

A.

Sharing data via pre-signed URLs without monitoring egress costs

B.

Migrating the dataset to Cloudflare R2 object storage before sharing

C.

Configure VPN connection between AWS and Azure for faster data sharing

D.

Using Delta Sharing without any additional configurations

Buy Now
Questions 46

A data engineer has left the organization. The data team needs to transfer ownership of the data engineer’s Delta tables to a new data engineer. The new data engineer is the lead engineer on the data team.

Assuming the original data engineer no longer has access, which of the following individuals must be the one to transfer ownership of the Delta tables in Data Explorer?

Options:

A.

Databricks account representative

B.

This transfer is not possible

C.

Workspace administrator

D.

New lead data engineer

E.

Original data engineer

Buy Now
Questions 47

A data engineer converts an external Delta table to a Unity Catalog managed table. A Structured Streaming job that reads from the table continues running during the conversion. After the conversion completes, the streaming job stops processing new records.

How should the data engineer resolve the issue?

Options:

A.

Restart the streaming job so that it uses the new managed-table location.

B.

Run REFRESH TABLE on the converted table to update the streaming checkpoint.

C.

Grant the streaming job additional permissions on the new managed-storage location.

D.

Delete the streaming checkpoint directory and reprocess the complete source from the beginning.

Buy Now
Questions 48

A data engineer is attempting to drop a Spark SQL table my_table. The data engineer wants to delete all table metadata and data.

They run the following command:

DROP TABLE IF EXISTS my_table

While the object no longer appears when they run SHOW TABLES, the data files still exist.

Which of the following describes why the data files still exist and the metadata files were deleted?

Options:

A.

The table’s data was larger than 10 GB

B.

The table’s data was smaller than 10 GB

C.

The table was external

D.

The table did not have a location

E.

The table was managed

Buy Now
Questions 49

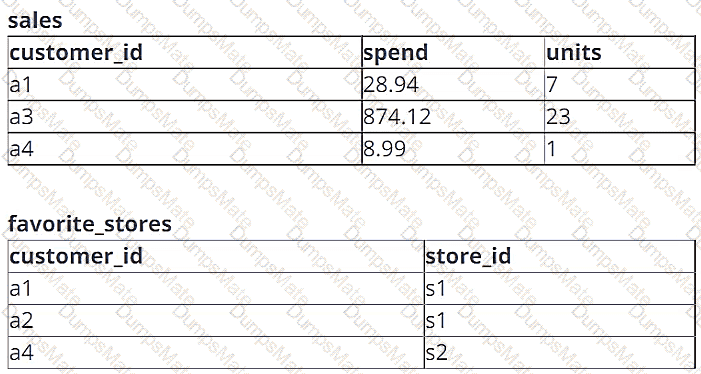
A data engineer is working with two tables. Each of these tables is displayed below in its entirety.

Databricks-Certified-Data-Engineer-Associate Question 49

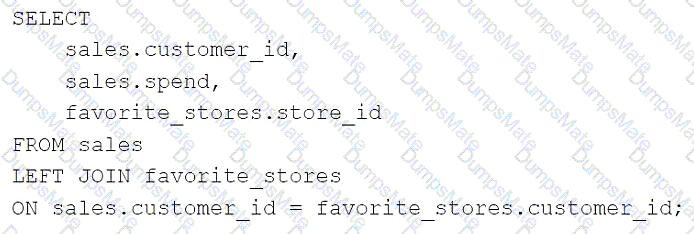
The data engineer runs the following query to join these tables together:

Databricks-Certified-Data-Engineer-Associate Question 49

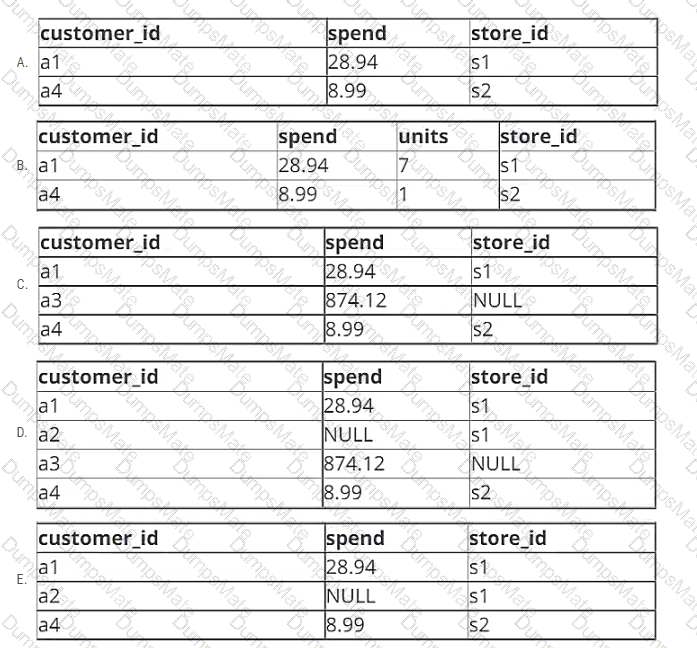
Which of the following will be returned by the above query?

Databricks-Certified-Data-Engineer-Associate Question 49

Options:

A.

Option A

B.

Option B

C.

Option C

D.

Option D

E.

Option E

Buy Now
Questions 50

A data engineer has a Python variable table_name that they would like to use in a SQL query. They want to construct a Python code block that will run the query using table_name.

They have the following incomplete code block:

____(f " SELECT customer_id, spend FROM {table_name} " )

Which of the following can be used to fill in the blank to successfully complete the task?

Options:

A.

spark.delta.sql

B.

spark.delta.table

C.

spark.table

D.

dbutils.sql

E.

spark.sql

Buy Now
Questions 51

Which of the following must be specified when creating a new Delta Live Tables pipeline?

Options:

A.

A key-value pair configuration

B.

The preferred DBU/hour cost

C.

A path to cloud storage location for the written data

D.

A location of a target database for the written data

E.

At least one notebook library to be executed

Buy Now
Questions 52

A data engineer needs to migrate the Unity Catalog external Delta table catalog.schema.sales while meeting the following requirements:

    Databricks must manage file cleanup after the table is dropped.

    The migration must minimize downtime while retaining the same table name, permissions, and history.

    Access must be enforced through the registered Unity Catalog table name.

Which action should the engineer take?

Options:

A.

Run ALTER TABLE catalog.schema.sales SET MANAGED.

B.

Run DROP TABLE catalog.schema.sales PURGE.

C.

Run ALTER TABLE catalog.schema.sales SET LOCATION.

D.

Create a new managed table using CREATE TABLE AS SELECT and manually migrate all workloads.

Buy Now
Questions 53

An organization has data stored across multiple external systems, including MySQL, Amazon Redshift, and Google BigQuery. The data engineer wants to perform analytics without ingesting data directly into Databricks, while ensuring unified governance and minimizing data duplication.

Which feature of Databricks enables querying these external data sources while maintaining centralized governance?

Options:

A.

Lakehouse Federation

B.

Databricks Connect

C.

MLflow

D.

Delta Lake

Buy Now
Questions 54

A data engineer needs to develop integration tests for an ETL process and deploy a version-controlled, packaged workflow into production using an external job scheduler.

Which tool should the data engineer use for this job?

Options:

A.

Databricks Command Line Interface

B.

Databricks Asset Bundles

C.

Databricks Connect

D.

Databricks Software Development Kit

Buy Now
Questions 55

A data engineer is cleaning a Bronze table that receives the same customer records from multiple source systems. Duplicate rows have the same customer_id and email values but different ingestion_timestamp values. The Silver table should contain only one record for each unique combination of customer_id and email.

Which PySpark operation correctly deduplicates the records based on the business keys?

Options:

A.

df.groupBy( " customer_id " , " email " ).agg(max( " ingestion_timestamp " ).alias( " latest_ts " ))

B.

df.distinct()

C.

df.select( " customer_id " , " email " ).distinct()

D.

df.dropDuplicates([ " customer_id " , " email " ])

Buy Now
Questions 56

A data analyst has a series of queries in a SQL program. The data analyst wants this program to run every day. They only want the final query in the program to run on Sundays. They ask for help from the data engineering team to complete this task.

Which of the following approaches could be used by the data engineering team to complete this task?

Options:

A.

They could submit a feature request with Databricks to add this functionality.

B.

They could wrap the queries using PySpark and use Python’s control flow system to determine when to run the final query.

C.

They could only run the entire program on Sundays.

D.

They could automatically restrict access to the source table in the final query so that it is only accessible on Sundays.

E.

They could redesign the data model to separate the data used in the final query into a new table.

Buy Now
Questions 57

Which method should a Data Engineer apply to ensure Workflows are being triggered on schedule?

Options:

A.

Scheduled Workflows require an always-running cluster, which is more expensive but reduces processing latency.

B.

Scheduled Workflows process data as it arrives at configured sources.

C.

Scheduled Workflows can reduce resource consumption and expense since the cluster runs only long enough to execute the pipeline.

D.

Scheduled Workflows run continuously until manually stopped.

Buy Now
Questions 58

A data engineer is attempting to grant a user access to a view. They successfully run the following command:

GRANT SELECT ON VIEW sales_catalog.market_data.summary

TO analyst_group;

However, the analyst still receives an “Insufficient Permissions” error when trying to query the view.

In which order should the engineer verify the hierarchy of securable objects to ensure that the analyst has the necessary usage permissions?

Options:

A.

METASTORE → TABLE → VIEW

B.

CATALOG → SCHEMA → VIEW

C.

WORKSPACE → CLUSTER → VIEW

D.

STORAGE CREDENTIAL → EXTERNAL LOCATION → VIEW

Buy Now
Questions 59

A data engineer triggers a scheduled job but finds that the new run was not executed. The run history shows that the run was skipped with a concurrency-related queue message.

Which configuration should the engineer investigate?

Options:

A.

The cluster spot-instance availability in the cloud provider

B.

The SQL warehouse permissions for the task

C.

The job-level max_concurrent_runs setting and whether queueing is enabled

D.

The task-level timeout_seconds configuration

Buy Now
Questions 60

A data engineer wants to schedule their Databricks SQL dashboard to refresh every hour, but they only want the associated SQL endpoint to be running when it is necessary. The dashboard has multiple queries on multiple datasets associated with it. The data that feeds the dashboard is automatically processed using a Databricks Job.

Which of the following approaches can the data engineer use to minimize the total running time of the SQL endpoint used in the refresh schedule of their dashboard?

Options:

A.

They can turn on the Auto Stop feature for the SQL endpoint.

B.

They can ensure the dashboard ' s SQL endpoint is not one of the included query ' s SQL endpoint.

C.

They can reduce the cluster size of the SQL endpoint.

D.

They can ensure the dashboard ' s SQL endpoint matches each of the queries ' SQL endpoints.

E.

They can set up the dashboard ' s SQL endpoint to be serverless.

Buy Now
Questions 61

A company has a strict 15-minute service-level agreement for updating its currency-exchange dashboard. Source data arrives in small increments every few minutes. The team needs a Lakeflow Jobs trigger strategy that keeps end-to-end latency within the SLA while minimizing compute cost and DBU consumption.

Which strategy is recommended?

Options:

A.

Use a scheduled trigger every 1 minute.

B.

Use a file-arrival trigger whenever a single JSON file arrives.

C.

Use a continuous trigger.

D.

Use a scheduled trigger every 12 minutes, with the streaming task configured to use Trigger.AvailableNow.

Buy Now
Questions 62

A data engineer works for an organization that must meet a stringent Service Level Agreement (SLA) that demands minimal runtime errors and high availability for its data processing pipelines. The data engineer wants to avoid the operational overhead of managing and tuning clusters.

Which architectural solution will meet the requirements?

Options:

A.

Implement a hybrid approach with scheduled batch jobs on custom cloud VMs.

B.

Use an auto-scaling cluster configured and monitored by the user.

C.

Utilize Databricks serverless compute that automatically optimizes resources and abstracts cluster management.

D.

Deploy a dedicated, manually managed cluster optimized by in-house IT staff.

Buy Now
Questions 63

A data engineering team is building a new data-transformation notebook. During development, the engineers need fast testing, quick code changes, and easy debugging. Later, the notebook will run nightly as a scheduled job without human intervention. The team wants to optimize for development speed.

Which compute should the team use during development?

Options:

A.

Classic jobs compute

B.

Interactive compute

C.

A SQL warehouse

D.

An instance pool

Buy Now
Questions 64

A team creates YAML manifests that declare jobs, resources, and dependencies, then deploys them to Databricks using the Databricks CLI . The deployment succeeds.

Which feature are they using?

Options:

A.

Databricks Asset Bundles

B.

GitHub

C.

Terraform

D.

DataOps

Buy Now
Questions 65

A data engineer has realized that they made a mistake when making a daily update to a table. They need to use Delta time travel to restore the table to a version that is 3 days old. However, when the data engineer attempts to time travel to the older version, they are unable to restore the data because the data files have been deleted.

Which of the following explains why the data files are no longer present?

Options:

A.

The VACUUM command was run on the table

B.

The TIME TRAVEL command was run on the table

C.

The DELETE HISTORY command was run on the table

D.

The OPTIMIZE command was nun on the table

E.

The HISTORY command was run on the table

Buy Now
Questions 66

A data engineer is cleaning a Bronze table. The requirement is to eliminate rows where either the customer_email field or the customer_phone field is NULL. The cleaning must be performed in one operation using a single method call.

Which PySpark approach supports filtering multiple columns for NULL values in one call?

Options:

A.

df.dropna(subset=[ " customer_email " , " customer_phone " ])

B.

df.where( " customer_email IS NOT NULL " ).where( " customer_phone IS NOT NULL " )

C.

df.na.drop(how= " all " )

D.

df.filter(col( " customer_email " ).isNotNull() & col( " customer_phone " ).isNotNull())

Buy Now
Questions 67

Which of the following is a benefit of the Databricks Lakehouse Platform embracing open source technologies?

Options:

A.

Cloud-specific integrations

B.

Simplified governance

C.

Ability to scale storage

D.

Ability to scale workloads

E.

Avoiding vendor lock-in

Buy Now
Questions 68

A data engineering team is using Kafka to capture event data and then ingest it into Databricks. The team wants to be able to see these historical events. Medallion architecture is already in place. The team wants to be mindful of costs.

Where should this historical event data be stored?

Options:

A.

Gold

B.

Silver

C.

Bronze

D.

Raw layer

Buy Now
Questions 69

An engineering manager wants to monitor the performance of a recent project using a Databricks SQL query. For the first week following the project’s release, the manager wants the query results to be updated every minute. However, the manager is concerned that the compute resources used for the query will be left running and cost the organization a lot of money beyond the first week of the project’s release.

Which of the following approaches can the engineering team use to ensure the query does not cost the organization any money beyond the first week of the project’s release?

Options:

A.

They can set a limit to the number of DBUs that are consumed by the SQL Endpoint.

B.

They can set the query’s refresh schedule to end after a certain number of refreshes.

C.

They cannot ensure the query does not cost the organization money beyond the first week of the project’s release.

D.

They can set a limit to the number of individuals that are able to manage the query’s refresh schedule.

E.

They can set the query’s refresh schedule to end on a certain date in the query scheduler.

Buy Now
Exam Name: Databricks Certified Data Engineer Associate Exam
Last Update: Oct 30, 2026
Questions: 230

PDF + Testing Engine

$42.5  $169.99

Testing Engine

$32.5  $129.99
buy now Databricks-Certified-Data-Engineer-Associate testing engine

PDF (Q&A)

$27.5  $109.99
buy now Databricks-Certified-Data-Engineer-Associate pdf
dumpsmate guaranteed to pass

24/7 Customer Support

DumpsMate's team of experts is always available to respond your queries on exam preparation. Get professional answers on any topic of the certification syllabus. Our experts will thoroughly satisfy you.

Site Secure
mcafee secure

TESTED 30 Oct 2026