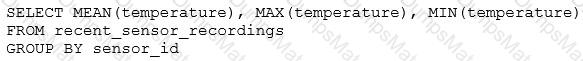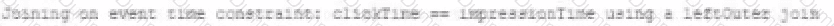Grab 75% Off This Black Friday: Use coupon code below to save on all exam bundles! - Ends in 0d 00h 00m 00s - Coupon code: 75only

Databricks-Certified-Professional-Data-Engineer Databricks Certified Data Engineer Professional Exam Questions and Answers

Questions 4

A Data engineer wants to run unit’s tests using common Python testing frameworks on python functions defined across several Databricks notebooks currently used in production.

How can the data engineer run unit tests against function that work with data in production?

Options:

A.

Run unit tests against non-production data that closely mirrors production

B.

Define and unit test functions using Files in Repos

C.

Define units test and functions within the same notebook

D.

Define and import unit test functions from a separate Databricks notebook

Buy Now
Questions 5

Which of the following is true of Delta Lake and the Lakehouse?

Options:

A.

Because Parquet compresses data row by row. strings will only be compressed when a character is repeated multiple times.

B.

Delta Lake automatically collects statistics on the first 32 columns of each table which are leveraged in data skipping based on query filters.

C.

Views in the Lakehouse maintain a valid cache of the most recent versions of source tables at all times.

D.

Primary and foreign key constraints can be leveraged to ensure duplicate values are never entered into a dimension table.

E.

Z-order can only be applied to numeric values stored in Delta Lake tables

Buy Now
Questions 6

A senior data engineer is planning large-scale data workflows. The task is to identify the considerations that form a foundation for creating scalable data models for managing large datasets. The team has listed Delta Lake capabilities and wants to determine which feature should not be considered as a core factor.

Which key feature can be ignored while evaluating Delta Lake?

Options:

A.

Delta Lake’s ability to process data in both batch and streaming modes seamlessly, providing flexibility in ingestion and processing.

B.

Delta Lake works with various data formats (Parquet, JSON, CSV) and integrates well with Spark and Databricks tools.

C.

Delta Lake optimizes metadata handling, efficiently managing billions of files and facilitating scalability to petabyte-scale datasets.

D.

Delta Lake provides limited support for monitoring and troubleshooting data pipelines, so relevant partner tools have to be identified and set up for enhanced operational efficiency.

Buy Now
Questions 7

A data engineer is creating a data ingestion pipeline to understand where customers are taking their rented bicycles during use. The engineer noticed that, over time, data being transmitted from the bicycle sensors fail to include key details like latitude and longitude. Downstream analysts need both the clean records and the quarantined records available for separate processing.

The data engineer already has this code:

import dlt

from pyspark.sql.functions import expr

rules = {

" valid_lat " : " (lat IS NOT NULL) " ,

" valid_long " : " (long IS NOT NULL) "

}

quarantine_rules = " NOT({}) " .format( " AND " .join(rules.values()))

@dlt.view

def raw_trips_data():

return spark.readStream.table( " ride_and_go.telemetry.trips " )

How should the data engineer meet the requirements to capture good and bad data?
Options:

A.

@dlt.table(name= " trips_data_quarantine " )

def trips_data_quarantine():

return (

spark.readStream.table( " raw_trips_data " )

.filter(expr(quarantine_rules))

)

B.

@dlt.view

@dlt.expect_or_drop( " lat_long_present " , " (lat IS NOT NULL AND long IS NOT NULL) " )

def trips_data_quarantine():

return spark.readStream.table( " ride_and_go.telemetry.trips " )

C.

@dlt.table

@dlt.expect_all_or_drop(rules)

def trips_data_quarantine():

return spark.readStream.table( " raw_trips_data " )

D.

@dlt.table(partition_cols=[ " is_quarantined " , ])

@dlt.expect_all(rules)

def trips_data_quarantine():

return (

spark.readStream.table( " raw_trips_data " )

.withColumn( " is_quarantined " , expr(quarantine_rules))

)

Buy Now
Questions 8

The business reporting team requires that data for their dashboards be updated every hour. The total processing time for the pipeline that extracts, transforms, and loads the data for their pipeline runs in 10 minutes. Assuming normal operating conditions, which configuration will meet their service-level agreement requirements with the lowest cost?

Options:

A.

Schedule a job to execute the pipeline once an hour on a dedicated interactive cluster.

B.

Schedule a job to execute the pipeline once an hour on a new job cluster.

C.

Schedule a Structured Streaming job with a trigger interval of 60 minutes.

D.

Configure a job that executes every time new data lands in a given directory.

Buy Now
Questions 9

A security analytics pipeline must enrich billions of raw connection logs with geolocation data. The join hinges on finding which IPv4 range each event’s address falls into.

Table 1: network_events (≈ 5 billion rows)

event_id ip_int

42 3232235777

Table 2: ip_ranges (≈ 2 million rows)

start_ip_int end_ip_int country

3232235520 3232236031 US

The query is currently very slow:

SELECT n.event_id, n.ip_int, r.country

FROM network_events n

JOIN ip_ranges r

ON n.ip_int BETWEEN r.start_ip_int AND r.end_ip_int;

Question:

Which change will most dramatically accelerate the query while preserving its logic?

Options:

A.

Increase spark.sql.shuffle.partitions from 200 to 10000.

B.

Add a range-join hint /*+ RANGE_JOIN(r, 65536) */.

C.

Force a sort-merge join with /*+ MERGE(r) */.

D.

Add a broadcast hint: /*+ BROADCAST(r) */ for ip_ranges.

Buy Now
Questions 10

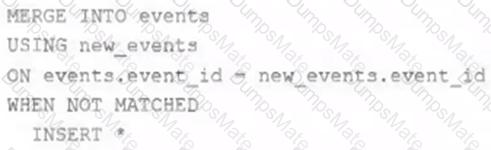
A junior data engineer on your team has implemented the following code block.

Databricks-Certified-Professional-Data-Engineer Question 10

The view new_events contains a batch of records with the same schema as the events Delta table. The event_id field serves as a unique key for this table.

When this query is executed, what will happen with new records that have the same event_id as an existing record?

Options:

A.

They are merged.

B.

They are ignored.

C.

They are updated.

D.

They are inserted.

E.

They are deleted.

Buy Now
Questions 11

Which statement describes the correct use of pyspark.sql.functions.broadcast?

Options:

A.

It marks a column as having low enough cardinality to properly map distinct values to available partitions, allowing a broadcast join.

B.

It marks a column as small enough to store in memory on all executors, allowing a broadcast join.

C.

It caches a copy of the indicated table on attached storage volumes for all active clusters within a Databricks workspace.

D.

It marks a DataFrame as small enough to store in memory on all executors, allowing a broadcast join.

E.

It caches a copy of the indicated table on all nodes in the cluster for use in all future queries during the cluster lifetime.

Buy Now
Questions 12

What is true for Delta Lake?

Options:

A.

Views in the Lakehouse maintain a valid cache of the most recent versions of source tables at all times.

B.

Delta Lake automatically collects statistics on the first 32 columns of each table, which are leveraged in data skipping based on query filters.

C.

Z-ORDER can only be applied to numeric values stored in Delta Lake tables.

D.

Primary and foreign key constraints can be leveraged to ensure duplicate values are never entered into a dimension table.

Buy Now
Questions 13

The data engineering team has configured a Databricks SQL query and alert to monitor the values in a Delta Lake table. The recent_sensor_recordings table contains an identifying sensor_id alongside the timestamp and temperature for the most recent 5 minutes of recordings.

The below query is used to create the alert:

Databricks-Certified-Professional-Data-Engineer Question 13

The query is set to refresh each minute and always completes in less than 10 seconds. The alert is set to trigger when mean (temperature) > 120 . Notifications are triggered to be sent at most every 1 minute.

If this alert raises notifications for 3 consecutive minutes and then stops, which statement must be true?

Options:

A.

The total average temperature across all sensors exceeded 120 on three consecutive executions of the query

B.

The recent_sensor_recordings table was unresponsive for three consecutive runs of the query

C.

The source query failed to update properly for three consecutive minutes and then restarted

D.

The maximum temperature recording for at least one sensor exceeded 120 on three consecutive executions of the query

E.

The average temperature recordings for at least one sensor exceeded 120 on three consecutive executions of the query

Buy Now
Questions 14

The DevOps team has configured a production workload as a collection of notebooks scheduled to run daily using the Jobs UI. A new data engineering hire is onboarding to the team and has requested access to one of these notebooks to review the production logic.

What are the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data?

Options:

A.

Can Manage

B.

Can Edit

C.

No permissions

D.

Can Read

E.

Can Run

Buy Now
Questions 15

A production workload incrementally applies updates from an external Change Data Capture feed to a Delta Lake table as an always-on Structured Stream job. When data was initially migrated for this table, OPTIMIZE was executed and most data files were resized to 1 GB. Auto Optimize and Auto Compaction were both turned on for the streaming production job. Recent review of data files shows that most data files are under 64 MB, although each partition in the table contains at least 1 GB of data and the total table size is over 10 TB.

Which of the following likely explains these smaller file sizes?

Options:

A.

Databricks has autotuned to a smaller target file size to reduce duration of MERGE operations

B.

Z-order indices calculated on the table are preventing file compaction

C Bloom filler indices calculated on the table are preventing file compaction

C.

Databricks has autotuned to a smaller target file size based on the overall size of data in the table

D.

Databricks has autotuned to a smaller target file size based on the amount of data in each partition

Buy Now
Questions 16

Two data engineers are working on the same Databricks notebook in separate branches. Both have edited the same section of code. When one tries to merge the other’s branch into their own using the Databricks Git folders UI, a merge conflict occurs on that notebook file. The UI highlights the conflict and presents options for resolution.

How should the data engineers resolve this merge conflict using Databricks Git folders?

Options:

A.

Abort the merge, discard all local changes, and try the merge operation again without reviewing the conflicting code.

B.

Delete the conflicted notebook file via the Databricks workspace UI, commit the deletion, and recreate the notebook from scratch in a new commit to bypass the conflict entirely.

C.

Use the Git CLI in the cluster’s web terminal to force-push the conflicted merge (git push -force), overriding the remote branch with the local version and discarding changes.

D.

Use the Git folders UI to manually edit the notebook file, selecting the desired lines from both versions and removing the conflict markers, then mark the conflict as resolved.

Buy Now
Questions 17

Which statement regarding stream-static joins and static Delta tables is correct?

Options:

A.

Each microbatch of a stream-static join will use the most recent version of the static Delta table as of each microbatch.

B.

Each microbatch of a stream-static join will use the most recent version of the static Delta table as of the job ' s initialization.

C.

The checkpoint directory will be used to track state information for the unique keys present in the join.

D.

Stream-static joins cannot use static Delta tables because of consistency issues.

E.

The checkpoint directory will be used to track updates to the static Delta table.

Buy Now
Questions 18

When evaluating the Ganglia Metrics for a given cluster with 3 executor nodes, which indicator would signal proper utilization of the VM ' s resources?

Options:

A.

The five Minute Load Average remains consistent/flat

B.

Bytes Received never exceeds 80 million bytes per second

C.

Network I/O never spikes

D.

Total Disk Space remains constant

E.

CPU Utilization is around 75%

Buy Now
Questions 19

A DLT pipeline includes the following streaming tables:

Raw_lot ingest raw device measurement data from a heart rate tracking device.

Bgm_stats incrementally computes user statistics based on BPM measurements from raw_lot.

How can the data engineer configure this pipeline to be able to retain manually deleted or updated records in the raw_iot table while recomputing the downstream table when a pipeline update is run?

Options:

A.

Set the skipChangeCommits flag to true on bpm_stats

B.

Set the SkipChangeCommits flag to true raw_lot

C.

Set the pipelines, reset, allowed property to false on bpm_stats

D.

Set the pipelines, reset, allowed property to false on raw_iot

Buy Now
Questions 20

A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Events are recorded once per minute per device.

df has the following schema: device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT

Code block:

df.withWatermark( " event_time " , " 10 minutes " )

.groupBy(

________,

" device_id "

)

.agg(

avg( " temp " ).alias( " avg_temp " ),

avg( " humidity " ).alias( " avg_humidity " )

)

.writeStream

.format( " delta " )

.saveAsTable( " sensor_avg " )

Which line of code correctly fills in the blank within the code block to complete this task?

Options:

A.

window( " event_time " , " 5 minutes " ).alias( " time " )

B.

to_interval( " event_time " , " 5 minutes " ).alias( " time " )

C.

" event_time "

D.

lag( " event_time " , " 5 minutes " ).alias( " time " )

Buy Now
Questions 21

When scheduling Structured Streaming jobs for production, which configuration automatically recovers from query failures and keeps costs low?

Options:

A.

Cluster: New Job Cluster;

Retries: Unlimited;

Maximum Concurrent Runs: Unlimited

B.

Cluster: New Job Cluster;

Retries: None;

Maximum Concurrent Runs: 1

C.

Cluster: Existing All-Purpose Cluster;

Retries: Unlimited;

Maximum Concurrent Runs: 1

D.

Cluster: New Job Cluster;

Retries: Unlimited;

Maximum Concurrent Runs: 1

E.

Cluster: Existing All-Purpose Cluster;

Retries: None;

Maximum Concurrent Runs: 1

Buy Now
Questions 22

A Delta Lake table in the Lakehouse named customer_parsams is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.

Immediately after each update succeeds, the data engineer team would like to determine the difference between the new version and the previous of the table.

Given the current implementation, which method can be used?

Options:

A.

Parse the Delta Lake transaction log to identify all newly written data files.

B.

Execute DESCRIBE HISTORY customer_churn_params to obtain the full operation metrics for the update, including a log of all records that have been added or modified.

C.

Execute a query to calculate the difference between the new version and the previous version using Delta Lake’s built-in versioning and time travel functionality.

D.

Parse the Spark event logs to identify those rows that were updated, inserted, or deleted.

Buy Now
Questions 23

To identify the top users consuming compute resources, a data engineering team needs to monitor usage within their Databricks workspace for better resource utilization and cost control. The team decided to use Databricks system tables, available under the System catalog in Unity Catalog, to gain detailed visibility into workspace activity.

Which SQL query should the team run from the System catalog to achieve this?

Options:

A.

SELECT sku_name,

identity_metadata.created_by AS user_email,

COUNT(usage_quantity) AS total_dbus

FROM system.billing.usage

GROUP BY user_email, sku_name

ORDER BY total_dbus DESC

LIMIT 10

B.

SELECT identity_metadata.run_as AS user_email,

SUM(usage_quantity) AS total_dbus

FROM system.billing.usage

GROUP BY user_email

ORDER BY total_dbus DESC

LIMIT 10

C.

SELECT sku_name,

identity_metadata.created_by AS user_email,

SUM(usage_quantity * usage_unit) AS total_dbus

FROM system.billing.usage

GROUP BY user_email, sku_name

ORDER BY total_dbus DESC

LIMIT 10

D.

SELECT sku_name,

usage_metadata.run_name AS user_email,

SUM(usage_quantity) AS total_dbus

FROM system.billing.usage

GROUP BY user_email, sku_name

ORDER BY total_dbus DESC

LIMIT 10

Buy Now
Questions 24

A data engineer has created a new cluster using shared access mode with default configurations. The data engineer needs to allow the development team access to view the driver logs if needed.

What are the minimal cluster permissions that allow the development team to accomplish this?

Options:

A.

CAN ATTACH TO

B.

CAN MANAGE

C.

CAN VIEW

D.

CAN RESTART

Buy Now
Questions 25

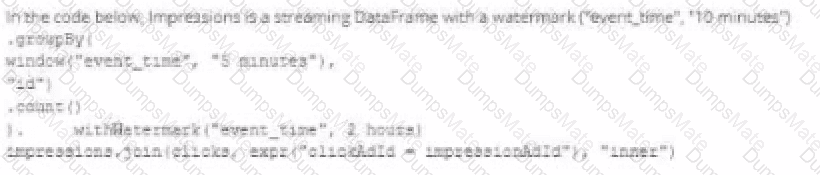
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.

Databricks-Certified-Professional-Data-Engineer Question 25

Which solution would improve the performance?

A)

Databricks-Certified-Professional-Data-Engineer Question 25

B)

Databricks-Certified-Professional-Data-Engineer Question 25

C)

Databricks-Certified-Professional-Data-Engineer Question 25

D)

Databricks-Certified-Professional-Data-Engineer Question 25

Options:

A.

Option A

B.

Option B

C.

Option C

D.

Option D

Buy Now
Questions 26

A platform team lead is responsible for automating SQL Warehouse usage attribution across business units. They need to identify warehouse usage at the individual user level and share a daily usage report with an executive team that includes business leaders from multiple departments.

How should the platform lead generate an automated report that can be shared daily?

Options:

A.

Use system tables to capture audit and billing usage data and share the queries with the executive team for manual execution.

B.

Use system tables to capture audit and billing usage data and create a dashboard with a daily refresh schedule shared with the executive team.

C.

Restrict users from running SQL queries unless they provide query details for attribution tracking.

D.

Let users run queries normally and have individual teams manually report usage to the executive team.

Buy Now
Questions 27

A data pipeline uses Structured Streaming to ingest data from kafka to Delta Lake. Data is being stored in a bronze table, and includes the Kafka_generated timesamp, key, and value. Three months after the pipeline is deployed the data engineering team has noticed some latency issued during certain times of the day.

A senior data engineer updates the Delta Table ' s schema and ingestion logic to include the current timestamp (as recoded by Apache Spark) as well the Kafka topic and partition. The team plans to use the additional metadata fields to diagnose the transient processing delays:

Which limitation will the team face while diagnosing this problem?

Options:

A.

New fields not be computed for historic records.

B.

Updating the table schema will invalidate the Delta transaction log metadata.

C.

Updating the table schema requires a default value provided for each file added.

D.

Spark cannot capture the topic partition fields from the kafka source.

Buy Now
Questions 28

A data team is implementing an append-only Delta Lake pipeline that processes both batch and streaming data . They want to ensure that schema changes in the source data are automatically incorporated without breaking the pipeline.

Which configuration should the team use when writing data to the Delta table?

Options:

A.

ignoreChanges = false

B.

mergeSchema = true

C.

overwriteSchema = true

D.

validateSchema = false

Buy Now
Questions 29

A data engineer wants to create a cluster using the Databricks CLI for a big ETL pipeline. The cluster should have five workers , one driver of type i3.xlarge, and should use the ' 14.3.x-scala2.12 ' runtime.

Which command should the data engineer use?

Options:

A.

databricks clusters create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name DataEngineer_cluster

B.

databricks clusters add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster

C.

databricks compute add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster

D.

databricks compute create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster

Buy Now
Questions 30

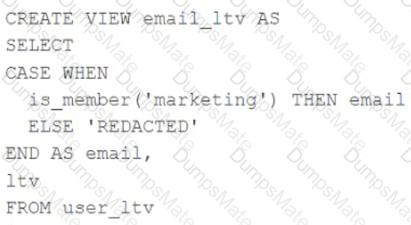
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.

The user_ltv table has the following schema:

email STRING, age INT, ltv INT

The following view definition is executed:

Databricks-Certified-Professional-Data-Engineer Question 30

An analyst who is not a member of the marketing group executes the following query:

SELECT * FROM email_ltv

Which statement describes the results returned by this query?

Options:

A.

Three columns will be returned, but one column will be named " redacted " and contain only null values.

B.

Only the email and itv columns will be returned; the email column will contain all null values.

C.

The email and ltv columns will be returned with the values in user itv.

D.

The email, age. and ltv columns will be returned with the values in user ltv.

E.

Only the email and ltv columns will be returned; the email column will contain the string " REDACTED " in each row.

Buy Now
Questions 31

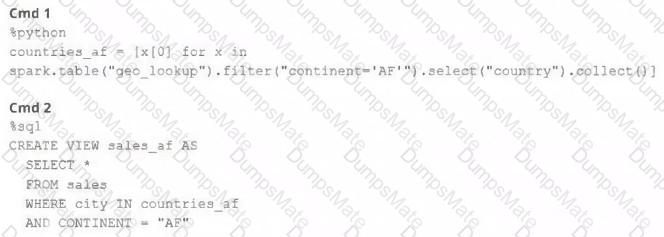
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in the geo_lookup table.

Before executing the code, running SHOW TABLES on the current database indicates the database contains only two tables: geo_lookup and sales .

Databricks-Certified-Professional-Data-Engineer Question 31

Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?

Options:

A.

Both commands will succeed. Executing show tables will show that countries at and sales at have been registered as views.

B.

Cmd 1 will succeed. Cmd 2 will search all accessible databases for a table or view named countries af: if this entity exists, Cmd 2 will succeed.

C.

Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable representing a PySpark DataFrame.

D.

Both commands will fail. No new variables, tables, or views will be created.

E.

Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable containing a list of strings.

Buy Now
Questions 32

A data engineer needs to install the PyYAML Python package within an air-gapped Databricks environment . The workspace has no direct internet access to PyPI. The engineer has downloaded the .whl file locally and wants it available automatically on all new clusters.

Which approach should the data engineer use?

Options:

A.

Upload the PyYAML .whl file to the user home directory and create a cluster-scoped init script to install it.

B.

Upload the PyYAML .whl file to a Unity Catalog Volume, ensure it’s allow-listed, and create a cluster-scoped init script that installs it from that path.

C.

Set up a private PyPI repository and install via pip index URL.

D.

Add the .whl file to Databricks Git Repos and assume automatic installation.

Buy Now
Questions 33

A small company based in the United States has recently contracted a consulting firm in India to implement several new data engineering pipelines to power artificial intelligence applications. All the company ' s data is stored in regional cloud storage in the United States.

The workspace administrator at the company is uncertain about where the Databricks workspace used by the contractors should be deployed.

Assuming that all data governance considerations are accounted for, which statement accurately informs this decision?

Options:

A.

Databricks runs HDFS on cloud volume storage; as such, cloud virtual machines must be deployed in the region where the data is stored.

B.

Databricks workspaces do not rely on any regional infrastructure; as such, the decision should be made based upon what is most convenient for the workspace administrator.

C.

Cross-region reads and writes can incur significant costs and latency; whenever possible, compute should be deployed in the same region the data is stored.

D.

Databricks leverages user workstations as the driver during interactive development; as such, users should always use a workspace deployed in a region they are physically near.

E.

Databricks notebooks send all executable code from the user ' s browser to virtual machines over the open internet; whenever possible, choosing a workspace region near the end users is the most secure.

Buy Now
Questions 34

In order to prevent accidental commits to production data, a senior data engineer has instituted a policy that all development work will reference clones of Delta Lake tables. After testing both deep and shallow clone, development tables are created using shallow clone.

A few weeks after initial table creation, the cloned versions of several tables implemented as Type 1 Slowly Changing Dimension (SCD) stop working. The transaction logs for the source tables show that vacuum was run the day before.

Why are the cloned tables no longer working?

Options:

A.

The data files compacted by vacuum are not tracked by the cloned metadata; running refresh on the cloned table will pull in recent changes.

B.

Because Type 1 changes overwrite existing records, Delta Lake cannot guarantee data consistency for cloned tables.

C.

The metadata created by the clone operation is referencing data files that were purged as invalid by the vacuum command

D.

Running vacuum automatically invalidates any shallow clones of a table; deep clone should always be used when a cloned table will be repeatedly queried.

Buy Now
Questions 35

The data engineering team has configured a job to process customer requests to be forgotten (have their data deleted). All user data that needs to be deleted is stored in Delta Lake tables using default table settings.

The team has decided to process all deletions from the previous week as a batch job at 1am each Sunday. The total duration of this job is less than one hour. Every Monday at 3am, a batch job executes a series of VACUUM commands on all Delta Lake tables throughout the organization.

The compliance officer has recently learned about Delta Lake ' s time travel functionality. They are concerned that this might allow continued access to deleted data.

Assuming all delete logic is correctly implemented, which statement correctly addresses this concern?

Options:

A.

Because the vacuum command permanently deletes all files containing deleted records, deleted records may be accessible with time travel for around 24 hours.

B.

Because the default data retention threshold is 24 hours, data files containing deleted records will be retained until the vacuum job is run the following day.

C.

Because Delta Lake time travel provides full access to the entire history of a table, deleted records can always be recreated by users with full admin privileges.

D.

Because Delta Lake ' s delete statements have ACID guarantees, deleted records will be permanently purged from all storage systems as soon as a delete job completes.

E.

Because the default data retention threshold is 7 days, data files containing deleted records will be retained until the vacuum job is run 8 days later.

Buy Now
Questions 36

A data architect has heard about lake ' s built-in versioning and time travel capabilities. For auditing purposes they have a requirement to maintain a full of all valid street addresses as they appear in the customers table.

The architect is interested in implementing a Type 1 table, overwriting existing records with new values and relying on Delta Lake time travel to support long-term auditing. A data engineer on the project feels that a Type 2 table will provide better performance and scalability.

Which piece of information is critical to this decision?

Options:

A.

Delta Lake time travel does not scale well in cost or latency to provide a long-term versioning solution.

B.

Delta Lake time travel cannot be used to query previous versions of these tables because Type 1 changes modify data files in place.

C.

Shallow clones can be combined with Type 1 tables to accelerate historic queries for long-term versioning.

D.

Data corruption can occur if a query fails in a partially completed state because Type 2 tables requires

Setting multiple fields in a single update.

Buy Now
Questions 37

The data engineer team is configuring environment for development testing, and production before beginning migration on a new data pipeline. The team requires extensive testing on both the code and data resulting from code execution, and the team want to develop and test against similar production data as possible.

A junior data engineer suggests that production data can be mounted to the development testing environments, allowing pre production code to execute against production data. Because all users have

Admin privileges in the development environment, the junior data engineer has offered to configure permissions and mount this data for the team.

Which statement captures best practices for this situation?

Options:

A.

Because access to production data will always be verified using passthrough credentials it is safe to mount data to any Databricks development environment.

B.

All developer, testing and production code and data should exist in a single unified workspace; creating separate environments for testing and development further reduces risks.

C.

In environments where interactive code will be executed, production data should only be accessible with read permissions; creating isolated databases for each environment further reduces risks.

D.

Because delta Lake versions all data and supports time travel, it is not possible for user error or malicious actors to permanently delete production data, as such it is generally safe to mount production data anywhere.

Buy Now
Questions 38

A data engineer wants to enforce the principle of least privilege when configuring ACLs for Databricks jobs in a collaborative workspace.

Which approach should the data engineer use?

Options:

A.

Grant CAN RUN permission to everyone and CAN MANAGE to a single admin group.

B.

Use only folder-level permissions and avoid setting permissions on individual jobs.

C.

Grant all users CAN MANAGE permission on all jobs to avoid access issues.

D.

Assign users only the minimum permission level (e.g., CAN RUN or CAN VIEW) required for their role on each job.

Buy Now
Questions 39

The DevOps team has configured a production workload as a collection of notebooks scheduled to run daily using the Jobs Ul. A new data engineering hire is onboarding to the team and has requested access to one of these notebooks to review the production logic.

What are the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data?

Options:

A.

Can manage

B.

Can edit

C.

Can run

D.

Can Read

Buy Now
Questions 40

Which statement describes Delta Lake Auto Compaction?

Options:

A.

An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 1 GB.

B.

Before a Jobs cluster terminates, optimize is executed on all tables modified during the most recent job.

C.

Optimized writes use logical partitions instead of directory partitions; because partition boundaries are only represented in metadata, fewer small files are written.

D.

Data is queued in a messaging bus instead of committing data directly to memory; all data is committed from the messaging bus in one batch once the job is complete.

E.

An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 128 MB.

Buy Now
Questions 41

The data architect has mandated that all tables in the Lakehouse should be configured as external (also known as " unmanaged " ) Delta Lake tables.

Which approach will ensure that this requirement is met?

Options:

A.

When a database is being created, make sure that the LOCATION keyword is used.

B.

When configuring an external data warehouse for all table storage, leverage Databricks for all ELT.

C.

When data is saved to a table, make sure that a full file path is specified alongside the Delta format.

D.

When tables are created, make sure that the EXTERNAL keyword is used in the CREATE TABLE statement.

E.

When the workspace is being configured, make sure that external cloud object storage has been mounted.

Buy Now
Questions 42

Which statement describes integration testing?

Options:

A.

Validates interactions between subsystems of your application

B.

Requires an automated testing framework

C.

Requires manual intervention

D.

Validates an application use case

E.

Validates behavior of individual elements of your application

Buy Now
Questions 43

A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings . The source data contains 100 unique fields in a highly nested JSON structure.

The silver_device_recordings table will be used downstream to power several production monitoring dashboards and a production model. At present, 45 of the 100 fields are being used in at least one of these applications.

The data engineer is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields.

Which of the following accurately presents information about Delta Lake and Databricks that may impact their decision-making process?

Options:

A.

The Tungsten encoding used by Databricks is optimized for storing string data; newly-added native support for querying JSON strings means that string types are always most efficient.

B.

Because Delta Lake uses Parquet for data storage, data types can be easily evolved by just modifying file footer information in place.

C.

Human labor in writing code is the largest cost associated with data engineering workloads; as such, automating table declaration logic should be a priority in all migration workloads.

D.

Because Databricks will infer schema using types that allow all observed data to be processed, setting types manually provides greater assurance of data quality enforcement.

E.

Schema inference and evolution on .Databricks ensure that inferred types will always accurately match the data types used by downstream systems.

Buy Now
Questions 44

A Delta Lake table representing metadata about content posts from users has the following schema:

    user_id LONG

    post_text STRING

    post_id STRING

    longitude FLOAT

    latitude FLOAT

    post_time TIMESTAMP

    date DATE

Based on the above schema, which column is a good candidate for partitioning the Delta Table?

Options:

A.

date

B.

user_id

C.

post_id

D.

post_time

Buy Now
Questions 45

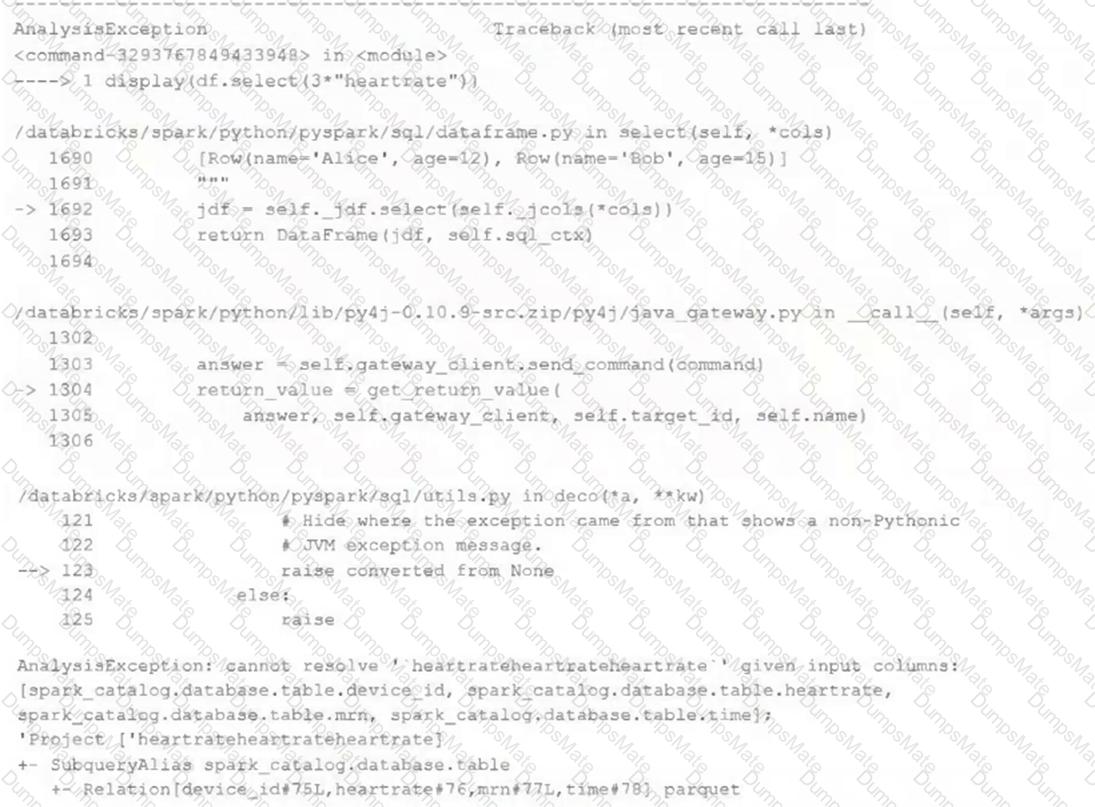
Review the following error traceback:

Databricks-Certified-Professional-Data-Engineer Question 45

Which statement describes the error being raised?

Options:

A.

The code executed was PvSoark but was executed in a Scala notebook.

B.

There is no column in the table named heartrateheartrateheartrate

C.

There is a type error because a column object cannot be multiplied.

D.

There is a type error because a DataFrame object cannot be multiplied.

E.

There is a syntax error because the heartrate column is not correctly identified as a column.

Buy Now
Questions 46

The data engineer team has been tasked with configured connections to an external database that does not have a supported native connector with Databricks. The external database already has data security configured by group membership. These groups map directly to user group already created in Databricks that represent various teams within the company.

A new login credential has been created for each group in the external database. The Databricks Utilities Secrets module will be used to make these credentials available to Databricks users.

Assuming that all the credentials are configured correctly on the external database and group membership is properly configured on Databricks, which statement describes how teams can be granted the minimum necessary access to using these credentials?

Options:

A.

‘’Read’’ permissions should be set on a secret key mapped to those credentials that will be used by a given team.

B.

No additional configuration is necessary as long as all users are configured as administrators in the workspace where secrets have been added.

C.

“Read” permissions should be set on a secret scope containing only those credentials that will be used by a given team.

D.

“Manage” permission should be set on a secret scope containing only those credentials that will be used by a given team.

Buy Now
Questions 47

The marketing team is looking to share data in an aggregate table with the sales organization, but the field names used by the teams do not match, and a number of marketing specific fields have not been approval for the sales org.

Which of the following solutions addresses the situation while emphasizing simplicity?

Options:

A.

Create a view on the marketing table selecting only these fields approved for the sales team alias the names of any fields that should be standardized to the sales naming conventions.

B.

Use a CTAS statement to create a derivative table from the marketing table configure a production jon to propagation changes.

C.

Add a parallel table write to the current production pipeline, updating a new sales table that varies as required from marketing table.

D.

Create a new table with the required schema and use Delta Lake ' s DEEP CLONE functionality to sync up changes committed to one table to the corresponding table.

Buy Now
Questions 48

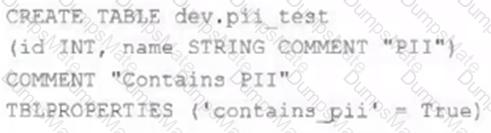
The data governance team has instituted a requirement that all tables containing Personal Identifiable Information (PH) must be clearly annotated. This includes adding column comments, table comments, and setting the custom table property " contains_pii " = true .

The following SQL DDL statement is executed to create a new table:

Databricks-Certified-Professional-Data-Engineer Question 48

Which command allows manual confirmation that these three requirements have been met?

Options:

A.

DESCRIBE EXTENDED dev.pii test

B.

DESCRIBE DETAIL dev.pii test

C.

SHOW TBLPROPERTIES dev.pii test

D.

DESCRIBE HISTORY dev.pii test

E.

SHOW TABLES dev

Buy Now
Questions 49

A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schema. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.

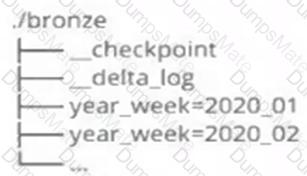
The proposed directory structure is displayed below:

Databricks-Certified-Professional-Data-Engineer Question 49

Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?

Options:

A.

No; Delta Lake manages streaming checkpoints in the transaction log.

B.

Yes; both of the streams can share a single checkpoint directory.

C.

No; only one stream can write to a Delta Lake table.

D.

Yes; Delta Lake supports infinite concurrent writers.

E.

No; each of the streams needs to have its own checkpoint directory.

Buy Now
Questions 50

To reduce storage and compute costs, the data engineering team has been tasked with curating a series of aggregate tables leveraged by business intelligence dashboards, customer-facing applications, production machine learning models, and ad hoc analytical queries.

The data engineering team has been made aware of new requirements from a customer-facing application, which is the only downstream workload they manage entirely. As a result, an aggregate table used by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added.

Which of the solutions addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed?

Options:

A.

Send all users notice that the schema for the table will be changing; include in the communication the logic necessary to revert the new table schema to match historic queries.

B.

Configure a new table with all the requisite fields and new names and use this as the source for the customer-facing application; create a view that maintains the original data schema and table name by aliasing select fields from the new table.

C.

Create a new table with the required schema and new fields and use Delta Lake ' s deep clone functionality to sync up changes committed to one table to the corresponding table.

D.

Replace the current table definition with a logical view defined with the query logic currently writing the aggregate table; create a new table to power the customer-facing application.

E.

Add a table comment warning all users that the table schema and field names will be changing on a given date; overwrite the table in place to the specifications of the customer-facing application.

Buy Now
Questions 51

The data engineer is using Spark ' s MEMORY_ONLY storage level.

Which indicators should the data engineer look for in the spark UI ' s Storage tab to signal that a cached table is not performing optimally?

Options:

A.

Size on Disk is > 0

B.

The number of Cached Partitions > the number of Spark Partitions

C.

The RDD Block Name included the ' ' annotation signaling failure to cache

D.

On Heap Memory Usage is within 75% of off Heap Memory usage

Buy Now
Questions 52

The data engineering team maintains the following code:

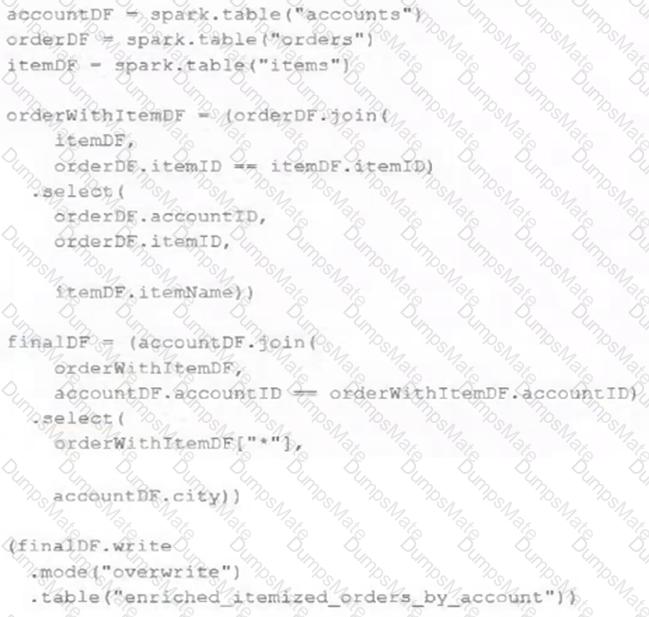
Databricks-Certified-Professional-Data-Engineer Question 52

Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?

Options:

A.

A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.

B.

The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.

C.

An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.

D.

An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.

E.

No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.

Buy Now
Questions 53

While reviewing a query ' s execution in the Databricks Query Profiler, a data engineer observes that the Top Operators panel shows a Sort operator with high Time Spent and Memory Peak metrics. The Spark UI also reports frequent data spilling .

How should the data engineer address this issue?

Options:

A.

Switch to a broadcast join to reduce memory usage.

B.

Repartition the DataFrame to a single partition before sorting.

C.

Convert the sort operation to a filter operation.

D.

Increase the number of shuffle partitions to better distribute data.

Buy Now
Questions 54

A query is taking too long to run. After investigating the Spark UI, the data engineer discovered a significant amount of disk spill . The compute instance being used has a core-to-memory ratio of 1:2.

What are the two steps the data engineer should take to minimize spillage? (Choose 2 answers)

Options:

A.

Choose a compute instance with a higher core-to-memory ratio.

B.

Choose a compute instance with more disk space.

C.

Increase spark.sql.files.maxPartitionBytes.

D.

Reduce spark.sql.files.maxPartitionBytes.

E.

Choose a compute instance with more network bandwidth.

Buy Now
Questions 55

A Delta Lake table with Change Data Feed (CDF) enabled in the Lakehouse named customer_churn_params is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources. The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours. Which approach would simplify the identification of these changed records?

Options:

A.

Apply the churn model to all rows in the customer_churn_params table, but implement logic to perform an upsert into the predictions table that ignores rows where predictions have not changed.

B.

Modify the overwrite logic to include a field populated by calling current_timestamp() as data are being written; use this field to identify records written on a particular date.

C.

Replace the current overwrite logic with a MERGE statement to modify only those records that have changed; write logic to make predictions on the changed records identified by the Change Data Feed.

D.

Convert the batch job to a Structured Streaming job using the complete output mode; configure a Structured Streaming job to read from the customer_churn_params table and incrementally predict against the churn model.

Buy Now
Questions 56

Which of the following technologies can be used to identify key areas of text when parsing Spark Driver log4j output?

Options:

A.

Regex

B.

Julia

C.

pyspsark.ml.feature

D.

Scala Datasets

E.

C++

Buy Now
Questions 57

A data engineer is running a groupBy aggregation on a massive user activity log grouped by user_id. A few users have millions of records, causing task skew and long runtimes.

Which technique will fix the skew in this aggregation?

Options:

A.

Use salting by adding a random prefix to skewed keys before aggregation, then aggregate again after removing the prefix.

B.

Increase the Spark driver memory and retry.

C.

Use reduceByKey instead of groupBy to avoid shuffles.

D.

Filter out the skewed users before the aggregation.

Buy Now
Questions 58

Which Python variable contains a list of directories to be searched when trying to locate required modules?

Options:

A.

importlib.resource path

B.

,sys.path

C.

os-path

D.

pypi.path

E.

pylib.source

Buy Now
Questions 59

A Structured Streaming job deployed to production has been resulting in higher than expected cloud storage costs. At present, during normal execution, each micro-batch of data is processed in less than 3 seconds; at least 12 times per minute, a micro-batch is processed that contains 0 records. The streaming write was configured using the default trigger settings. The production job is currently scheduled alongside many other Databricks jobs in a workspace with instance pools provisioned to reduce start-up time for jobs with batch execution. Holding all other variables constant and assuming records need to be processed in less than 10 minutes, which adjustment will meet the requirement?

Options:

A.

Set the trigger interval to 500 milliseconds; setting a small but non-zero trigger interval ensures that the source is not queried too frequently.

B.

Set the trigger interval to 3 seconds; the default trigger interval is consuming too many records per batch, resulting in spill to disk that can increase volume costs.

C.

Set the trigger interval to 10 minutes; each batch calls APIs in the source storage account, so decreasing trigger frequency to the maximum allowable threshold should minimize this cost.

D.

Use the trigger once option and configure a Databricks job to execute the query every 10 minutes; this approach minimizes costs for both compute and storage.

Buy Now
Questions 60

A data engineer is creating a daily reporting job. There are two reporting notebooks—one for weekdays and one for weekends. An “if/else condition” task is configured as {{job.start_time.is_weekday}} == true to route the job to either the weekday or weekend notebook tasks. The same job would be used across multiple time zones.

Which action should a senior data engineer take upon reviewing the job to merge or reject the pull request?

Options:

A.

Reject, as the {{job.start_time.is_weekday}} is for the UTC timezone .

B.

Reject, as the {{job.start_time.is_weekday}} is not a valid value reference.

C.

Merge, as the job configuration looks good.

D.

Reject, as they should use {{job.trigger_time.is_weekday}} instead.

Buy Now
Exam Name: Databricks Certified Data Engineer Professional Exam
Last Update: Nov 13, 2026
Questions: 285

PDF + Testing Engine

$42.5  $169.99

Testing Engine

$32.5  $129.99
buy now Databricks-Certified-Professional-Data-Engineer testing engine

PDF (Q&A)

$27.5  $109.99
buy now Databricks-Certified-Professional-Data-Engineer pdf
dumpsmate guaranteed to pass

24/7 Customer Support

DumpsMate's team of experts is always available to respond your queries on exam preparation. Get professional answers on any topic of the certification syllabus. Our experts will thoroughly satisfy you.

Site Secure

mcafee secure

TESTED 13 Nov 2026