Grab 75% Off This Black Friday: Use coupon code below to save on all exam bundles! - Ends in 0d 00h 00m 00s - Coupon code: 75only

Databricks-Certified-Data-Analyst-Associate Databricks Certified Data Analyst Associate Exam Questions and Answers

Questions 4

A managed table and an unmanaged external table were both created in Databricks SQL, and data was ingested into each table. Later, both tables were dropped.

What is the status of data for each of those tables?

Options:

A.

The data in both tables were deleted.

B.

The data in the managed table were deleted, and the data in the unmanaged external table were left untouched.

C.

The data in the unmanaged external table were deleted, and the data in the managed table were left untouched.

D.

The data in both tables were left untouched.

Buy Now
Questions 5

Delta Lake stores table data as a series of data files, but it also stores a lot of other information.

Which of the following is stored alongside data files when using Delta Lake?

Options:

A.

None of these

B.

Table metadata, data summary visualizations, and owner account information

C.

Table metadata

D.

Data summary visualizations

E.

Owner account information

Buy Now

Databricks-Certified-Data-Analyst-Associate Report Card

Questions 6

A data engineer is maintaining a data pipeline. Upon data ingestion, the data engineer notices that the source data is starting to have a lower level of quality. The data engineer would like to automate the process of monitoring the quality level.

Which of the following tools can the data engineer use to solve this problem?

Options:

A.

Unity Catalog

B.

Data Explorer

C.

Delta Lake

D.

Delta Live Tables

E.

Auto Loader

Buy Now
Questions 7

A data analyst is working with gold-layer tables to complete an ad-hoc project. A stakeholder has provided the analyst with an additional dataset that can be used to augment the gold-layer tables already in use.

Which of the following terms is used to describe this data augmentation?

Options:

A.

Data testing

B.

Ad-hoc improvements

C.

Last-mile

D.

Last-mile ETL

E.

Data enhancement

Buy Now
Questions 8

Which of the following statements about a refresh schedule is incorrect?

Options:

A.

A query can be refreshed anywhere from 1 minute lo 2 weeks

B.

Refresh schedules can be configured in the Query Editor.

C.

A query being refreshed on a schedule does not use a SQL Warehouse (formerly known as SQL Endpoint).

D.

A refresh schedule is not the same as an alert.

E.

You must have workspace administrator privileges to configure a refresh schedule

Buy Now
Questions 9

A data engineer has been using a Databricks SQL dashboard to monitor the cleanliness of the input data to a data analytics dashboard for a retail use case. The job has a Databricks SQL query that returns the number of store-level records where sales is equal to zero. The data engineer wants their entire team to be notified via a messaging webhook whenever this value is greater than 0.

Which of the following approaches can the data engineer use to notify their entire team via a messaging webhook whenever the number of stores with $0 in sales is greater than zero?

Options:

A.

They can set up an Alert with a custom template.

B.

They can set up an Alert with a new email alert destination.

C.

They can set up an Alert with one-time notifications.

D.

They can set up an Alert with a new webhook alert destination.

E.

They can set up an Alert without notifications.

Buy Now
Questions 10

Which of the following is a benefit of Databricks SQL using ANSI SQL as its standard SQL dialect?

Options:

A.

It has increased customization capabilities

B.

It is easy to migrate existing SQL queries to Databricks SQL

C.

It allows for the use of Photon ' s computation optimizations

D.

It is more performant than other SQL dialects

E.

It is more compatible with Spark ' s interpreters

Buy Now
Questions 11

A data analyst has created a user-defined function using the following line of code:

CREATE FUNCTION price(spend DOUBLE, units DOUBLE)

RETURNS DOUBLE

RETURN spend / units;

Which of the following code blocks can be used to apply this function to the customer_spend and customer_units columns of the table customer_summary to create column customer_price?

Options:

A.

SELECT PRICE customer_spend, customer_units AS customer_price FROM customer_summary

B.

SELECT price FROM customer_summary

C.

SELECT function(price(customer_spend, customer_units)) AS customer_price FROM customer_summary

D.

SELECT double(price(customer_spend, customer_units)) AS customer_price FROM customer_summary

E.

SELECT price(customer_spend, customer_units) AS customer_price FROM customer_summary

Buy Now
Questions 12

A distributed team of data analysts share computing resources on an interactive cluster with autoscaling configured. In order to better manage costs and query throughput, the workspace administrator is hoping to evaluate whether cluster upscaling is caused by many concurrent users or resource-intensive queries.

In which location can one review the timeline for cluster resizing events?

Options:

A.

Workspace audit logs

B.

Driver’s log file

C.

Ganglia

D.

Cluster Event Log

E.

Executor’s log file

Buy Now
Questions 13

An analyst has been asked to combine the data in two tables: suppliers and new_suppliers. It is possible that some of the supplier_id values match in both tables, meaning those suppliers have already been added to the suppliers table. If that is the case, the data should be unchanged.

Which command will combine the two tables without duplicating the rows with the same supplier_id?

Options:

A.

Option AMERGE INTO suppliersUSING new_suppliersON suppliers.supplier_id = new_suppliers.supplier_idWHEN NOT MATCHED THEN INSERT *;

B.

Option BCOPY INTO suppliersUSING new_suppliersON suppliers.supplier_id = new_suppliers.supplier_idWHEN NOT MATCHED THEN INSERT *;

C.

Option CUPDATE suppliersUSING new_suppliersON suppliers.supplier_id = new_suppliers.supplier_idWHEN NOT MATCHED THEN INSERT *;

D.

Option DINSERT INTO suppliersUSING new_suppliersON suppliers.supplier_id = new_suppliers.supplier_idWHEN NOT MATCHED THEN INSERT *;

Buy Now
Questions 14

A data analyst is attempting to drop a table my_table. The analyst wants to delete all table metadata and data.

They run the following command:

DROP TABLE IF EXISTS my_table;

While the object no longer appears when they run SHOW TABLES, the data files still exist.

Which of the following describes why the data files still exist and the metadata files were deleted?

Options:

A.

The table ' s data was larger than 10 GB

B.

The table did not have a location

C.

The table was external

D.

The table ' s data was smaller than 10 GB

E.

The table was managed

Buy Now
Questions 15

Which statement about visualizations is true?

Options:

A.

All visualizations must use the same data in order to be included in the same Databricks SQL dashboard.

B.

Line charts are the preferred visualization type for categorical data.

C.

Different visualizations can be used to tell different stories about the data.

D.

There is no difference between the bar chart and a histogram in Databricks SQL.

Buy Now
Questions 16

Which open-source project helps to enable the data lakehouse by adding organization, reliability, performance, and data governance to data lake architectures?

Options:

A.

MLflow

B.

Apache Spark

C.

Delta Lake

D.

Databricks SQL

Buy Now
Questions 17

A data analyst wants to generate insights from large, complex datasets. The analyst needs to quickly understand the meaning of various data columns, ask questions in natural language, and receive AI-driven recommendations for optimizing data queries and workflows.

Which Databricks component is primarily responsible for enabling these capabilities?

Options:

A.

Data Intelligence Engine

B.

Unity Catalog

C.

Genie Spaces

D.

Databricks Assistant

Buy Now
Questions 18

A data analyst has two data sources that are providing similar but complementary information. The analyst wants to combine these sources of data into a single, comprehensive dataset for ongoing use for their team in a variety of different projects.

Which term is used to describe this type of work?

Options:

A.

Last-mile ETL

B.

Ad-hoc improvements

C.

Data testing

D.

Data blending

Buy Now
Questions 19

In which of the following situations will the mean value and median value of variable be meaningfully different?

Options:

A.

When the variable contains no outliers

B.

When the variable contains no missing values

C.

When the variable is of the boolean type

D.

When the variable is of the categorical type

E.

When the variable contains a lot of extreme outliers

Buy Now
Questions 20

What is used as a compute resource for Databricks SQL?

Options:

A.

Single-node clusters

B.

Downstream BI tools integrated with Databricks SQL

C.

SQL warehouses

D.

Standard clusters

Buy Now
Questions 21

A data analyst has come across a column in a table that contains personally identifiable information (PII). The data analyst should not have access to this type of PII data.

How should the data analyst proceed?

Options:

A.

Stop working with the data and delete the table and any existing metadata or data files.

B.

Stop working with the data and proceed with the project using other data.

C.

Stop working with the data and notify their supervisor to ensure the data is handled following organizational and legal best practices.

D.

Drop the column containing PII data and continue with the project without notifying anybody.

Buy Now
Questions 22

Which of the following is a benefit of the Databricks Lakehouse Platform embracing open source technologies?

Options:

A.

Cloud-specific integrations

B.

Simplified governance

C.

Ability to scale storage

D.

Ability to scale workloads

E.

Avoiding vendor lock-in

Buy Now
Questions 23

Where can an admin or data owner grant database, table, and view permissions to a group?

Options:

A.

Dashboard

B.

Data

C.

SQL Warehouses

D.

Settings

Buy Now
Questions 24

A data analyst is working with a nested array column products in table transactions. The analyst wants to return the first item in the array for each row.

The data analyst is using the following incomplete command:

SELECT

transaction_id,

_____ AS first_product

FROM transactions;

Which line of code should the data analyst use to fill in the blank so that it successfully completes the task?

Options:

A.

products.1

B.

products.0

C.

products[0]

D.

products[1]

Buy Now
Questions 25

What is an advantage of using a Delta Lake-based data lakehouse over classic enterprise data warehouse solutions?

Options:

A.

Open-source formats

B.

Schema enforcement

C.

ACID transactions

D.

Generic optimizations

Buy Now
Questions 26

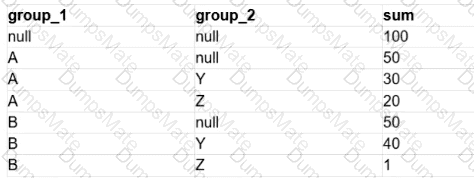
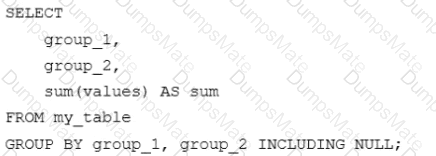
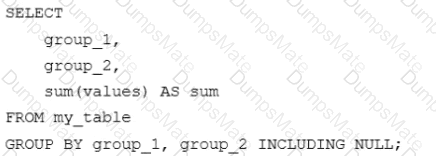
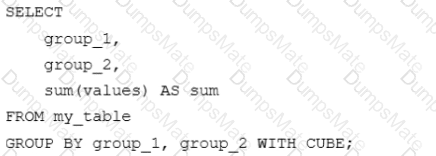
A data analyst is processing a complex aggregation on a table with zero null values and the query returns the following result:

Databricks-Certified-Data-Analyst-Associate Question 26

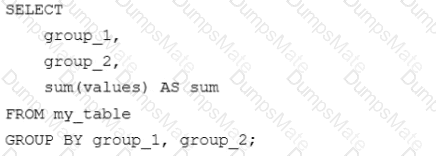
Which query did the analyst execute in order to get this result?

A)

Databricks-Certified-Data-Analyst-Associate Question 26

B)

Databricks-Certified-Data-Analyst-Associate Question 26

C)

Databricks-Certified-Data-Analyst-Associate Question 26

D)

Databricks-Certified-Data-Analyst-Associate Question 26

Options:

A.

Option A

B.

Option B

C.

Option C

D.

Option D

Buy Now
Questions 27

Which of the following is stored in the Databricks customer’s cloud account?

Options:

A.

Databricks web application

B.

Cluster management metadata

C.

Repos

D.

Data

E.

Notebooks

Buy Now
Questions 28

A data analyst has recently joined a new team that uses Databricks SQL, but the analyst has never used Databricks before. The analyst wants to know where in Databricks SQL they can write and execute SQL queries.

On which of the following pages can the analyst write and execute SQL queries?

Options:

A.

Data page

B.

Dashboards page

C.

Queries page

D.

Alerts page

E.

SQL Editor page

Buy Now
Questions 29

Which statement describes descriptive statistics?

Options:

A.

A branch of statistics that uses a variety of data analysis techniques to infer properties of an underlying distribution of probability.

B.

A branch of statistics that uses summary statistics to categorically describe and summarize data.

C.

A branch of statistics that uses summary statistics to quantitatively describe and summarize data.

D.

A branch of statistics that uses quantitative variables that must take on a finite or countably infinite set of values.

Buy Now
Questions 30

A data team has been given a series of projects by a consultant that need to be implemented in the Databricks Lakehouse Platform.

Which of the following projects should be completed in Databricks SQL?

Options:

A.

Testing the quality of data as it is imported from a source

B.

Tracking usage of feature variables for machine learning projects

C.

Combining two data sources into a single, comprehensive dataset

D.

Segmenting customers into like groups using a clustering algorithm

E.

Automating complex notebook-based workflows with multiple tasks

Buy Now
Questions 31

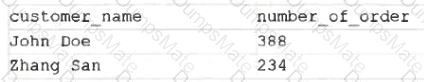
A data analyst wants the following output:

Databricks-Certified-Data-Analyst-Associate Question 31

Which statement will produce this output?

A)

Databricks-Certified-Data-Analyst-Associate Question 31

B)

Databricks-Certified-Data-Analyst-Associate Question 31

C)

Databricks-Certified-Data-Analyst-Associate Question 31

D)

Databricks-Certified-Data-Analyst-Associate Question 31

Options:

A.

Option A

B.

Option B

C.

Option C

D.

Option D

Buy Now
Questions 32

A data analyst has been asked to use the below table sales_table to rank products within region by the sales.

Input table:

region product sales

WEST A 1880.59

EAST A 2045.99

EAST B 4583.23

WEST B 3391.19

The result of the query should look like this:

region product rank

EAST B 1

EAST A 2

WEST B 1

WEST A 2

Which query will accomplish this task?

Options:

A.

SELECT region, product, RANK() OVER ( ORDER BY sales DESC ) AS rankFROM sales_table;

B.

SELECT region, product, RANK() OVER ( PARTITION BY product ORDER BY sales DESC ) AS rankFROM sales_table;

C.

SELECT region, product, RANK() OVER ( PARTITION BY region ) AS rankFROM sales_table;

D.

SELECT region, product, RANK() OVER ( PARTITION BY region ORDER BY sales DESC ) AS rankFROM sales_table;

E.

Option A

F.

Option B

G.

Option C

Buy Now
Questions 33

What is a benefit of using Databricks SQL for business intelligence (Bl) analytics projects instead of using third-party Bl tools?

Options:

A.

Computations, data, and analytical tools on the same platform

B.

Advanced dashboarding capabilities

C.

Simultaneous multi-user support

D.

Automated alerting systems

Buy Now
Questions 34

Data engineers and data analysts are working together on a data pipeline. The data engineer is working on the raw, bronze, and silver layers of the pipeline using Python, and the data analyst is working on the gold layer of the pipeline using SQL. The raw source of the pipeline is a streaming input. They now want to migrate their pipeline to use Delta Live Tables.

Which of the following changes will need to be made to the pipeline when migrating to Delta Live Tables?

Options:

A.

The pipeline can have different notebook sources in SQL and Python.

B.

The pipeline will need to be written entirely in SQL.

C.

The pipeline will need to use a batch source in place of a streaming source.

D.

The pipeline will need to be written entirely in Python.

Buy Now
Questions 35

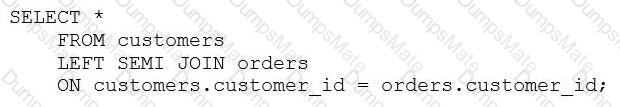
Consider the following two statements:

Statement 1:

Databricks-Certified-Data-Analyst-Associate Question 35

Statement 2:

Which of the following describes how the result sets will differ for each statement when they are run in Databricks SQL?

Options:

A.

The first statement will return all data from the customers table and matching data from the orders table. The second statement will return all data from the orders table and matching data from the customers table. Any missing data will be filled in with NULL.

B.

When the first statement is run, only rows from the customers table that have at least one match with the orders table on customer_id will be returned. When the second statement is run, only those rows in the customers table that do not have at least one match with the orders table on customer_id will be returned.

C.

There is no difference between the result sets for both statements.

D.

Both statements will fail because Databricks SQL does not support those join types.

E.

When the first statement is run, all rows from the customers table will be returned and only the customer_id from the orders table will be returned. When the second statement is run, only those rows in the customers table that do not have at least one match with the orders table on customer_id will be returned.

Buy Now
Exam Name: Databricks Certified Data Analyst Associate Exam
Last Update: Nov 15, 2026
Questions: 118

PDF + Testing Engine

$42.5  $169.99

Testing Engine

$32.5  $129.99
buy now Databricks-Certified-Data-Analyst-Associate testing engine

PDF (Q&A)

$27.5  $109.99
buy now Databricks-Certified-Data-Analyst-Associate pdf
dumpsmate guaranteed to pass

24/7 Customer Support

DumpsMate's team of experts is always available to respond your queries on exam preparation. Get professional answers on any topic of the certification syllabus. Our experts will thoroughly satisfy you.

Site Secure
mcafee secure

TESTED 15 Nov 2026